Skip to content

feat(session): 新增 /fast,使用 OpenAI 优先服务档位(Fast 模式) - #1740

Open
zszz3 wants to merge 2 commits into
vastsa:mainfrom
zszz3:feat/fast-mode-1657
Open

zszz3 wants to merge 2 commits into
vastsa:mainfrom
zszz3:feat/fast-mode-1657

Conversation

@zszz3

@zszz3 zszz3 commented Oct 17, 2026 •

Copy link
Copy Markdown
Contributor

Closes #1657

做了什么

给订阅制 ChatGPT(Codex)和 OpenAI Responses 接口加上 Fast 模式:请求会携带 service_tier: "priority",即 OpenAI 的优先档位。回复更快,但订阅会更快消耗额度,API key 则按更高的 token 单价计费。

按照讨论中的建议,能不能开由模型设置决定,开不开由会话决定:

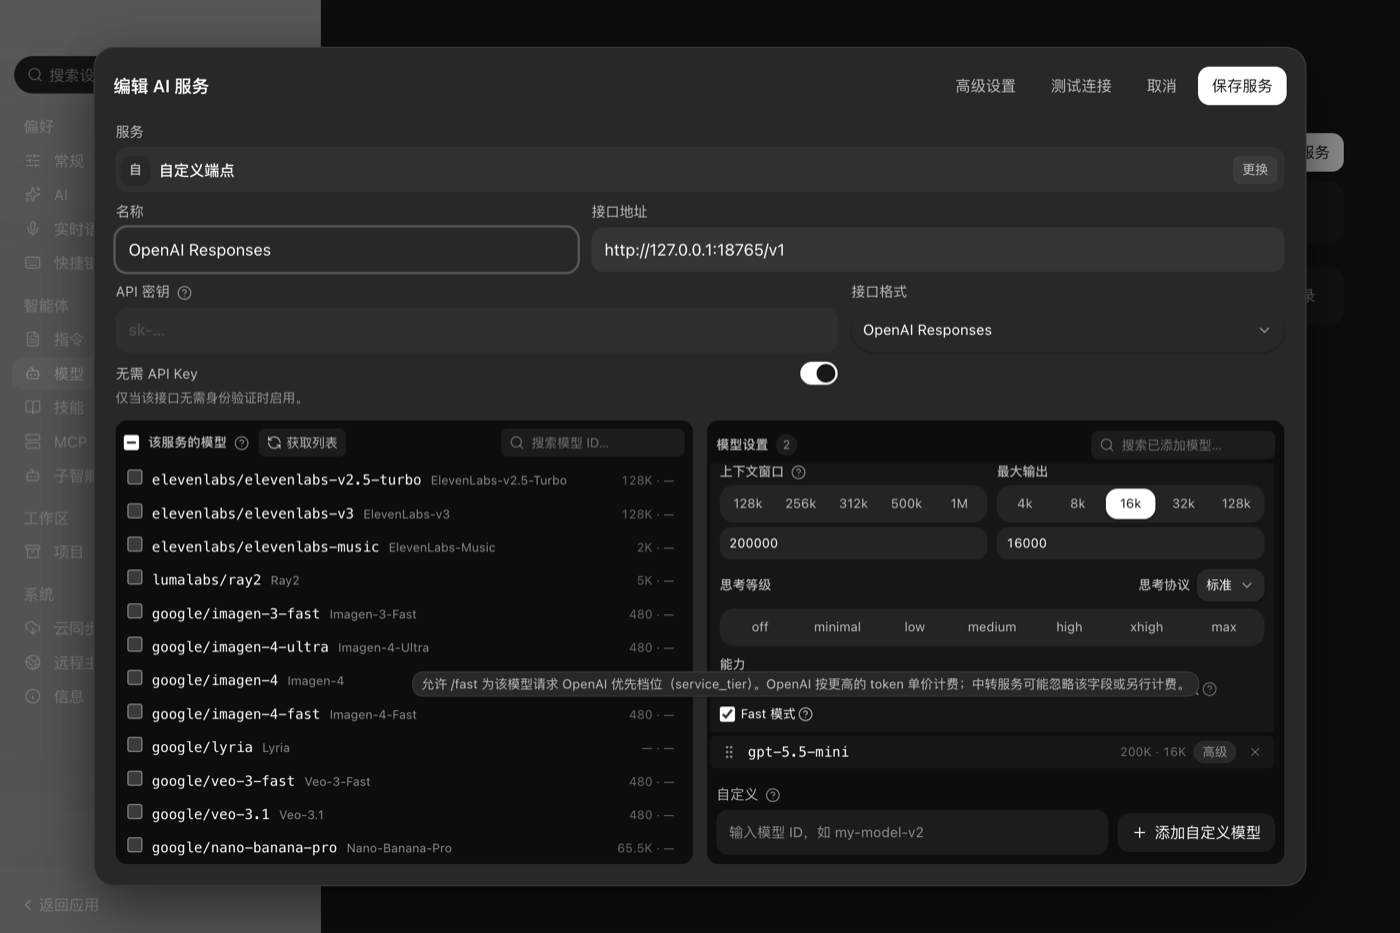
  • 设置 → 模型 → 编辑服务 → 某个模型的「高级」→ 能力 → 勾选「Fast 模式」:按模型保存,默认关闭。只在 Responses 协议(Codex 订阅、OpenAI Responses 及其中转)上可勾选;Chat Completions 等协议上是灰的。问号提示会说明该连接上的计费方式。
  • 在输入框发送 /fast:为当前会话开关 Fast。状态会保存,重启后保留,fork 会复制;在空白首页发送时,记在新任务草稿上,带进创建出的会话。
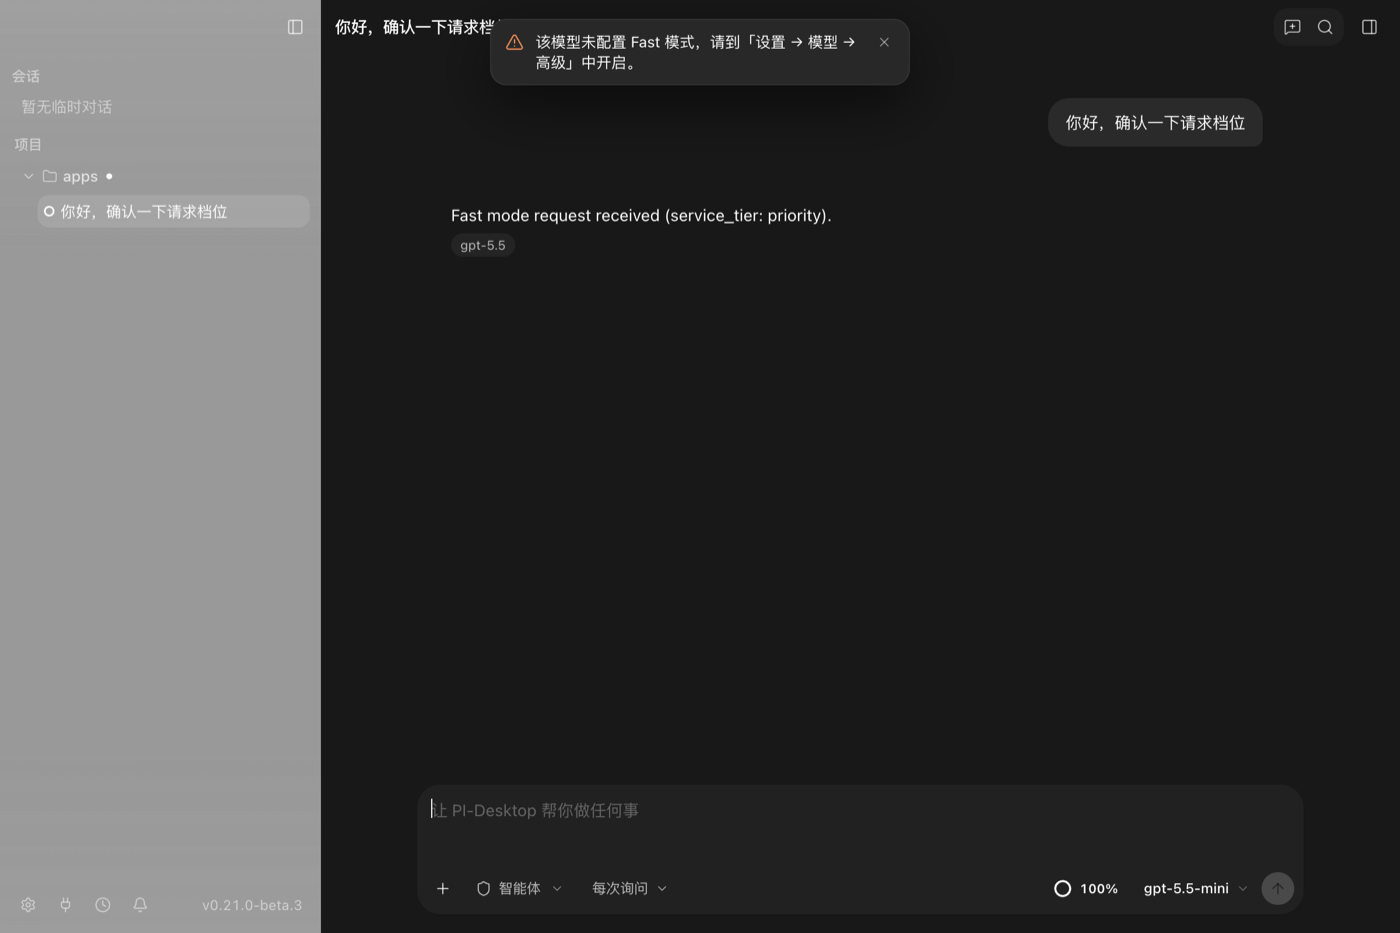
  • 当前模型没在设置里开启时,/fast 不改任何状态,只提示「该模型未配置 Fast 模式,请到「设置 → 模型 → 高级」中开启」。
  • 开启后,输入框的模型标签旁会显示 ⚡;切到未配置的模型时标识随之消失,请求也不再带该字段。
  • 只有主回合请求会带这个字段;子代理、上下文压缩和插件的一次性请求保持默认档位,避免后台任务消耗加速额度。远程会话不支持。

后续如何使用

  1. 打开 设置 → 模型,在 ChatGPT(Plus/Pro)账号或 OpenAI Responses 服务上点「编辑」。
  2. 在右侧「模型设置」里展开要用的模型的 高级,在「能力」中勾选 Fast 模式,保存服务。
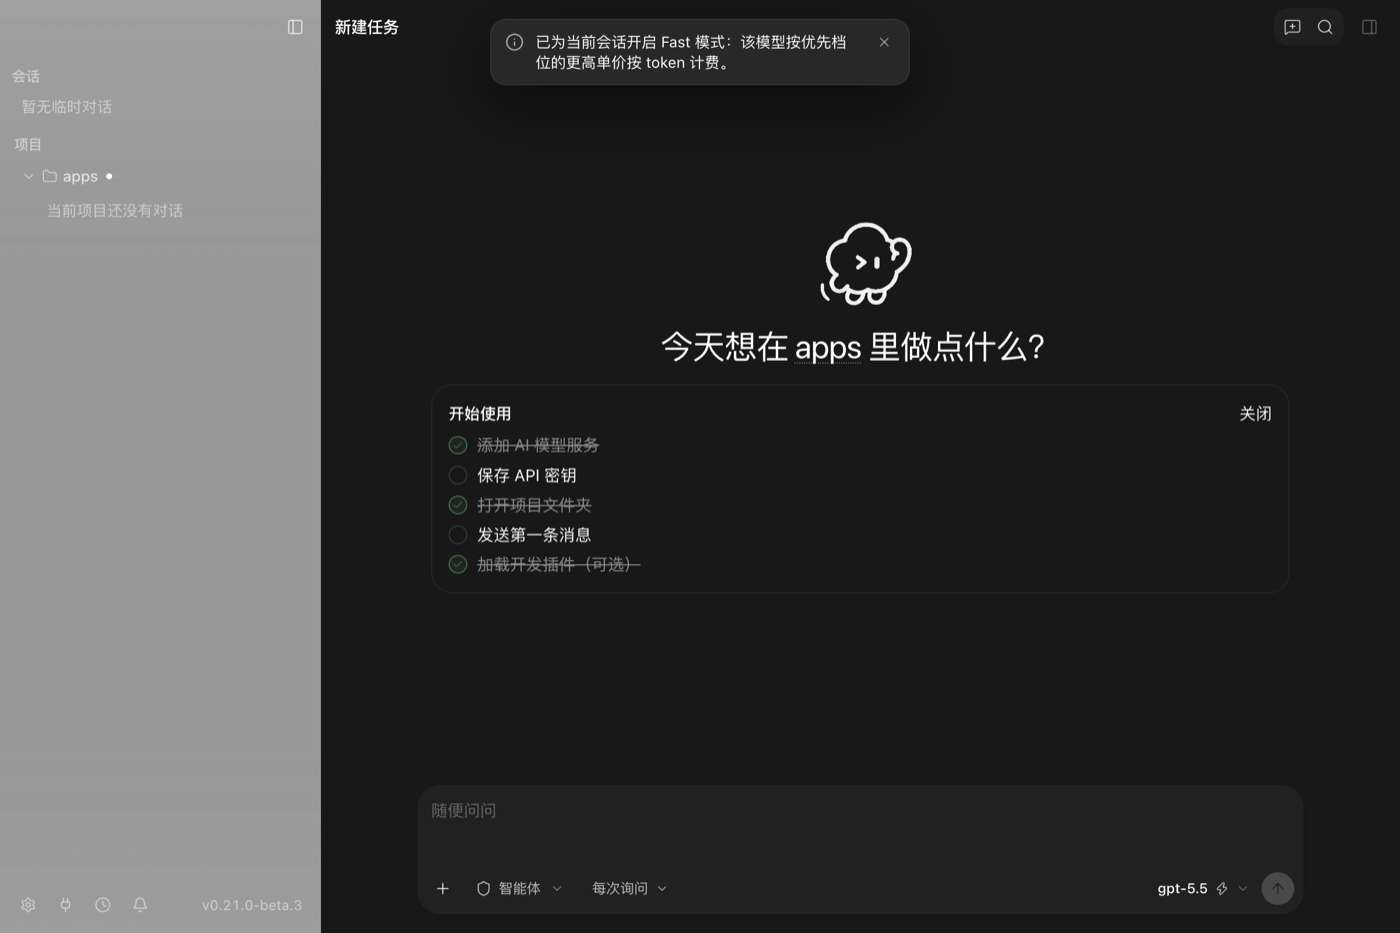
  3. 回到对话,选中这个模型,在输入框发送 /fast:弹出「已为当前会话开启 Fast 模式」,模型标签旁出现 ⚡。
  4. 正常聊天即可;该会话之后的每一轮都会使用优先档位。
  5. 再次发送 /fast 即可关闭。其他会话不受影响,新会话默认关闭。

截图

隔离 profile 加本地假 Responses 端点(无 API key),端点会把收到的 service_tier 回显在回复里。

1. 设置 → 模型 → 高级 → 能力:Fast 模式(附计费提示)
settings

2. /fast 开启:提示 + 模型标签 ⚡
on

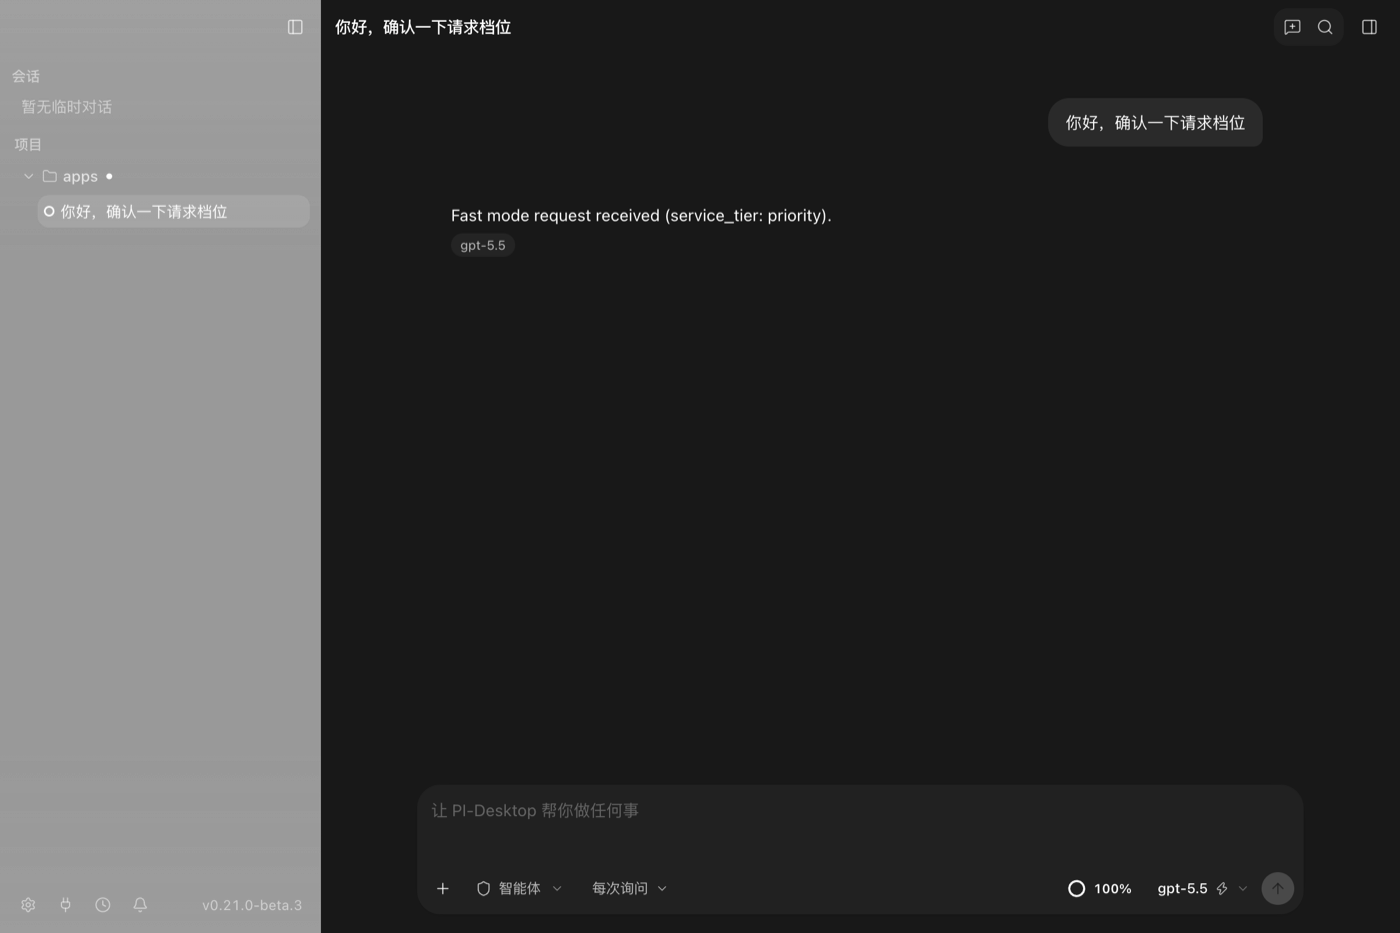
3. 发送消息:请求体带 service_tier: priority(端点记录:{"path":"/v1/responses","model":"gpt-5.5","service_tier":"priority"})
request

4. 切到未配置的模型后发送 /fast:提示去设置里配置
not configured

实现

  • 模型绑定:ModelBinding.fastModeAllowed,存在已有的 provider config_json 里(与 nativeWebSearch 相同),无需迁移;provider 同步、复制与导入链路都已带上该字段。
  • 会话:sessions.fast_mode(schema v25,仅新增一列,迁移前备份 v24)。session.create / session.configure 接受可选布尔值 fastMode,缺省保留原值,非布尔值返回 INVALID_PARAMS。fork 复制该值,定时任务和委托子会话从关闭开始。远程会话拒绝该字段。
  • 启动:session-launch 只有在「会话开启 + 用户保存的模型绑定允许」时才向 sidecar 传 fastMode: true。这里直接读用户保存的绑定,因为 Codex 这类 OAuth 账号的模型配置不经过它。
  • 运行时:主回合在实际协议为 openai-codex-responses / openai-responses 时传入 pi-ai 原生的 serviceTier: "priority",由适配器写入 service_tier 并按档位计价。pi-ai 的 streamSimple 组装参数时会丢掉 serviceTier,所以在已有的 pi-ai 补丁里加了一行转发(dist/api/simple-options.js),并在 SimpleStreamOptions 类型里声明该字段。
  • 文档:ADR 0331,以及 builtin commands、数据存储(v25)、IPC、host RPC、provider 模型系统等中英文 spec,E2E-FAST-MODE 场景和 changelog。

验证

  • 新增测试:host-core v24→v25 迁移、会话保存/fork、RPC 参数校验;shared 协议规则;runtime 经真实 pi-ai streamSimple(Responses / Completions)检查请求体;session-launch 判断;/fast 用户路径(草稿 → 创建会话、开关、未配置、远程会话、Composer 标识);设置页契约。
  • pnpm lint、desktop typecheck、cargo fmt --check、cargo clippy 通过。
  • 全量测试:shared 1278、desktop 4078 个通过(另 12 个 Electron 用户路径测试在补齐 Electron 二进制后单独重跑通过)。有两个本地已知失败与本改动无关:host-core data_relocation(macOS 本地环境),以及 agent-runtime subagent-fallback 的 429 用例超时(撤掉本改动后在同一 main 上同样失败)。
  • 截图流程即手动端到端验证:设置 → /fast → 实际请求体。未使用真实 ChatGPT 账号发送请求。

风险

  • 中转或自定义 Responses 端点可能忽略该字段或另行计费,设置提示里已说明,由用户自行勾选。
  • 像 GitHub Copilot 这样跨多种协议的账号,设置页按服务的接口格式判断是否可勾选;运行时仍按每次请求的实际协议过滤,不支持的协议不会带该字段。

ChatGPT subscribers and OpenAI API users can ask for a faster priority
tier (Responses `service_tier: "priority"`), which costs more plan
limits or a higher per-token price. PI-Desktop never requested a tier.

Model settings now own whether a model may use it: a per-model "Fast
mode" opt-in, enabled for Responses wires, stored in the existing
binding JSON. The cost is a per-conversation choice, so `/fast` toggles
a persisted session switch (schema v25, additive). On a model that is
not configured, `/fast` stores nothing and points to Settings → Models →
Advanced. Launch sends Fast mode only when both are on, and only main
turns carry the field; subagents and compaction keep the default tier.

closes vastsa#1657
@muzimu217

Copy link
Copy Markdown
Contributor

Feasibility check for the implementation as described: @earendil-works/pi-ai 1.1.0 already ships the service_tier plumbing in its OpenAI Responses adapter (options.serviceTier + applyServiceTierPricing, api/openai-responses-shared.js), so no upstream pi-ai change is needed — the work stays in PI-Desktop's per-model capability flag and the per-session /fast toggle, exactly as scoped. The scoping decisions look right too: per-model opt-in (Responses protocol only), per-session toggle, main-turn-only (keeping subagent/compaction/plugin calls on default tier avoids silent quota burn).

@muzimu217

Copy link
Copy Markdown
Contributor

The failing check is the transcript-render probe inside the Trusted extensions Electron E2E job: longHistory fails with "stream stole the reader's scroll position" (render/runtimeSlot/smoothText all pass). For context: main's latest run of the same job (run 39036112194, today 13:19 UTC) is green, and this PR touches the session/composer fast-mode path rather than transcript scrolling — so this looks like the known scroll-position race in the long-history probe rather than a regression. A re-run may just clear it; if it reproduces, worth checking whether the ⚡ badge changes composer height enough to shift the reader's scroll anchoring.

pi-ai's Responses and Codex adapters already accept `serviceTier`, send
it as `service_tier`, and price the tier the response reports. Only
`streamSimple` dropped the option while building its base options, which
is why the first version wrote the field through a payload hook.

Forward `serviceTier` in the existing pi-ai patch and pass the native
option on main turns instead. The request bytes are unchanged, and the
Codex adapter can now price a priority request even when the backend
echoes the default tier.
@zszz3

zszz3 commented Oct 18, 2026

Copy link
Copy Markdown
Contributor Author

Thanks — good catch on the native option. Updated in d4c7795:

  • The runtime now passes pi-ai's native serviceTier: "priority" on main turns (Responses / Codex wires only) instead of writing service_tier through a payload hook, so the adapters also apply their own tier pricing — including the Codex case where the backend echoes default for a priority request.
  • One nuance: the adapters' low-level stream() reads serviceTier, but streamSimple() (what the runtime uses) rebuilds its options in buildBaseOptions and dropped the field. I added a one-line forward to the existing patches/@earendil-works__pi-ai@1.1.0.patch (plus the SimpleStreamOptions type), and packages/agent-runtime/src/fast-mode.test.ts now asserts service_tier: "priority" in the request body through the real streamSimple. Request bytes are unchanged.

On the E2E failure: agreed it's the longHistory scroll race. The ⚡ mark only renders while Fast mode is on (never in that scenario) and sits inline in the existing model chip, so it doesn't change composer height. Locally node scripts/e2e-transcript-render.mjs passes all phases, including longHistory. I can't re-run jobs from the fork — could a maintainer re-run it if the new run hits it again?

This branch has not been deployed

No deployments
Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Labels

None yet

Projects

None yet

Development

Successfully merging this pull request may close these issues.

[Feature] 订阅制的openai,有没有1.5x加速的模式

2 participants