
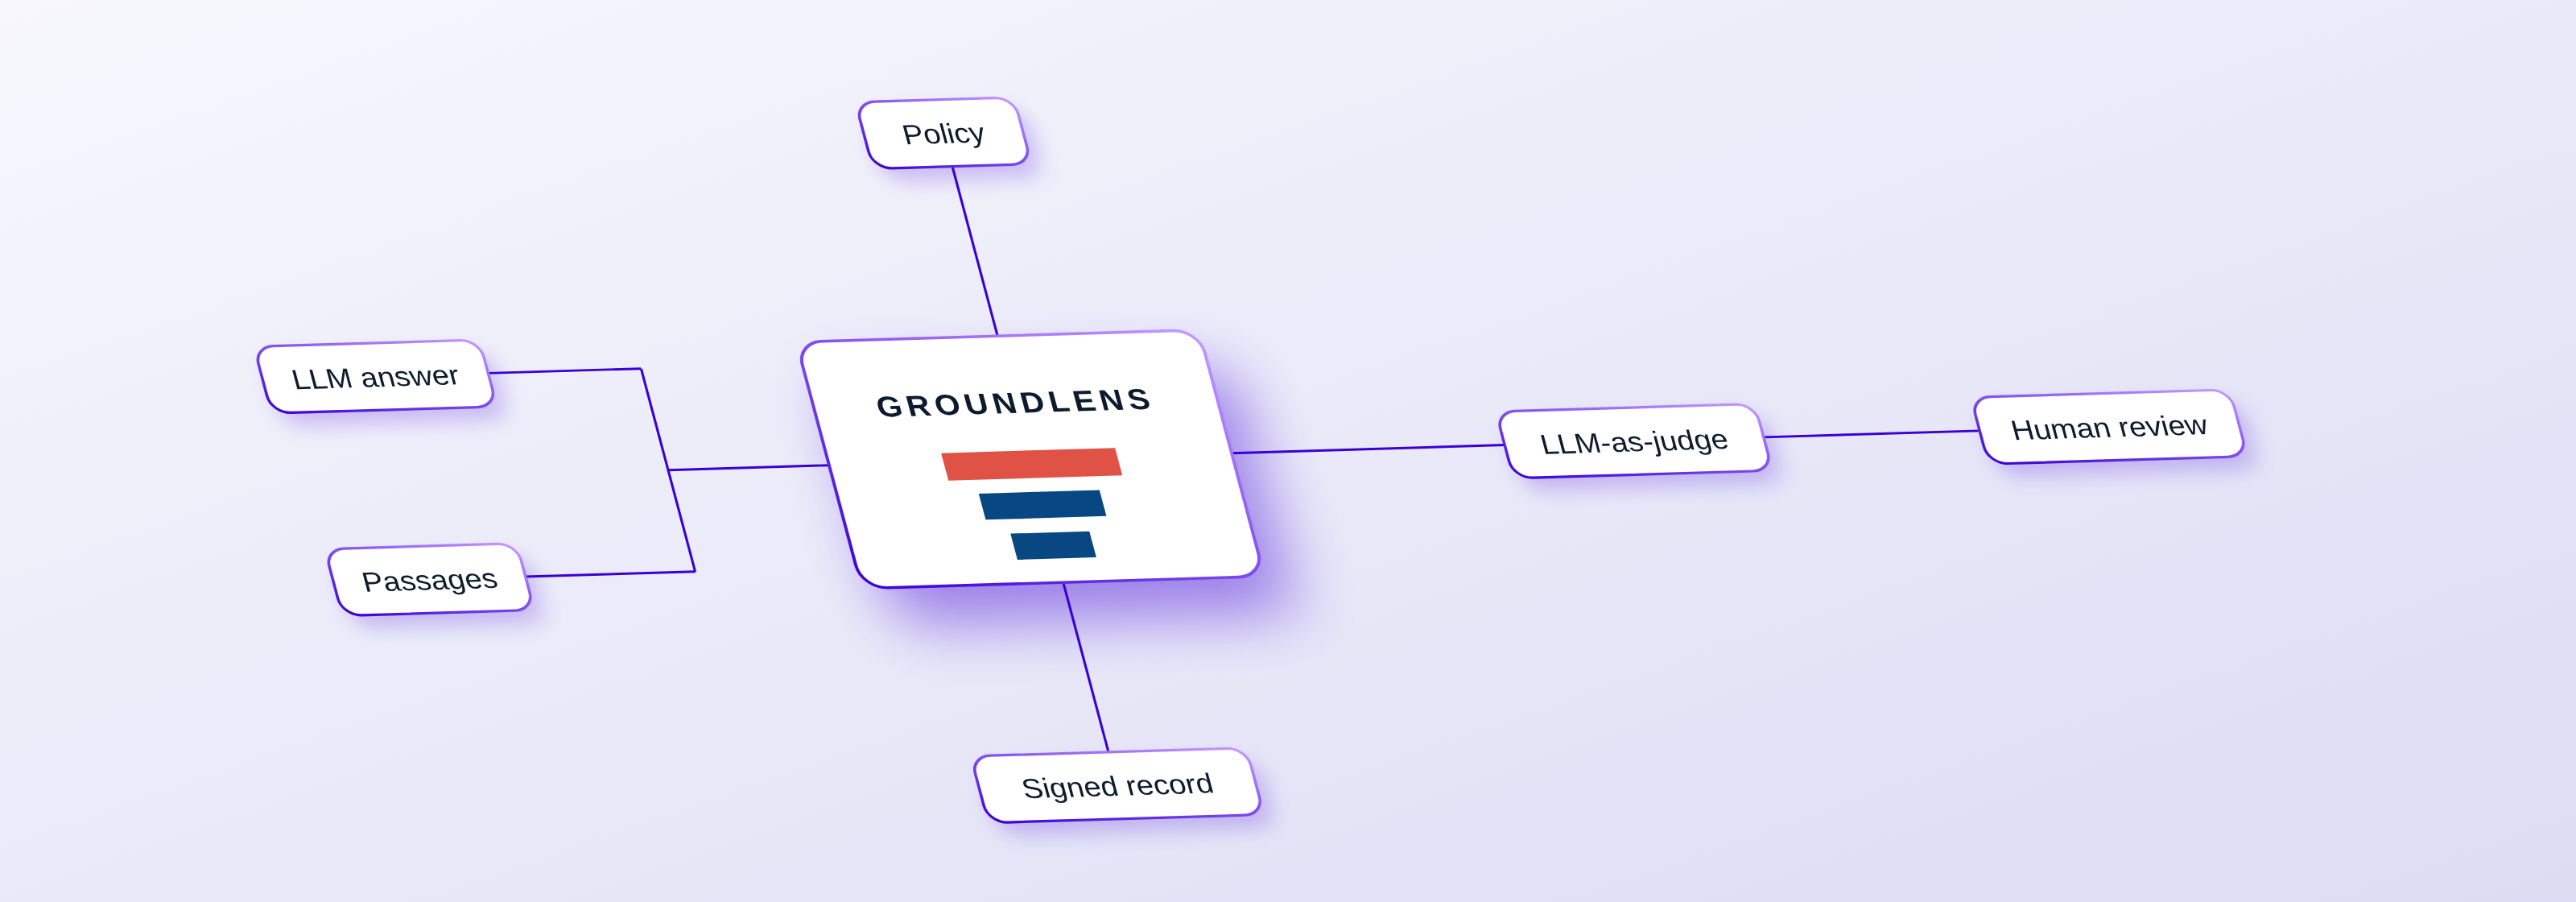


GroundLens checks AI answers against your documents:
the figures, who they are about, and whether they answer the question.
On financial answers it had never seen, it stopped 3 of 4 wrong ones;
on public claims with numbers, half of the unsupported ones.
About 10 ms per check, deterministic, no LLM in the loop.1
| Keep it. GroundLens runs the exact checks first, and a FAIL never reaches the judge. Your judge only sees the answers the exact checks could not reject. | Deterministic | Exact checks first, no LLM judge needed |
| Provable | PASS, REVIEW or FAIL, with a signed record | |
| Measured | Measure the error rate of what passes, on your answers | |
| Portable | Rust engine: the same hash on every OS |
Works with




# pip install groundlens
import groundlens as gl

verifier = gl.Verifier(sink=gl.sinks.jsonl("records/"))
record = verifier.check(answer="Revenue was €42.1 million.", passages=["Revenue reached €41.2 million."])
print(record.decision, record.reasons)
FAIL ['c2: groundlens.numeric contradicted: €42.1 million not in sources; nearest 41200000 EUR in ctx-0 (relative distance 0.021)']
Runs locally: no account, no API key, no model, no network. The signed record is in records/ before check returns.
The same check, wired into your stack:
Langfuse · pip install "groundlens[langfuse]"
from langfuse import get_client
verifier = gl.Verifier(sink=gl.sinks.jsonl("records/"), observers=[gl.integrations.langfuse(get_client())])
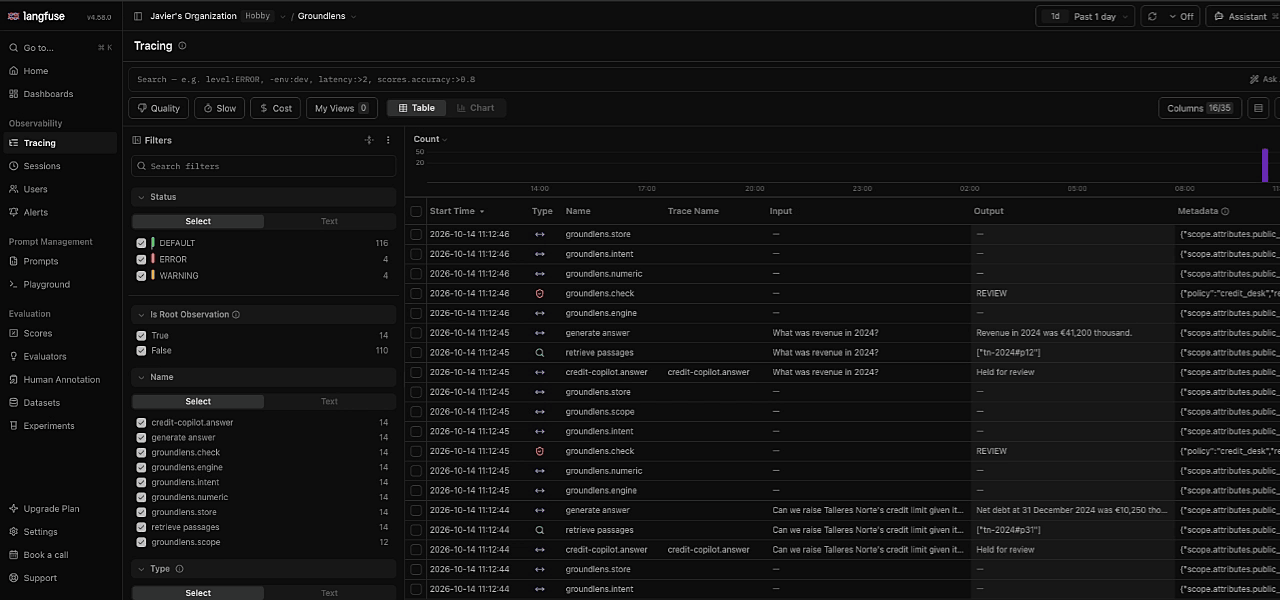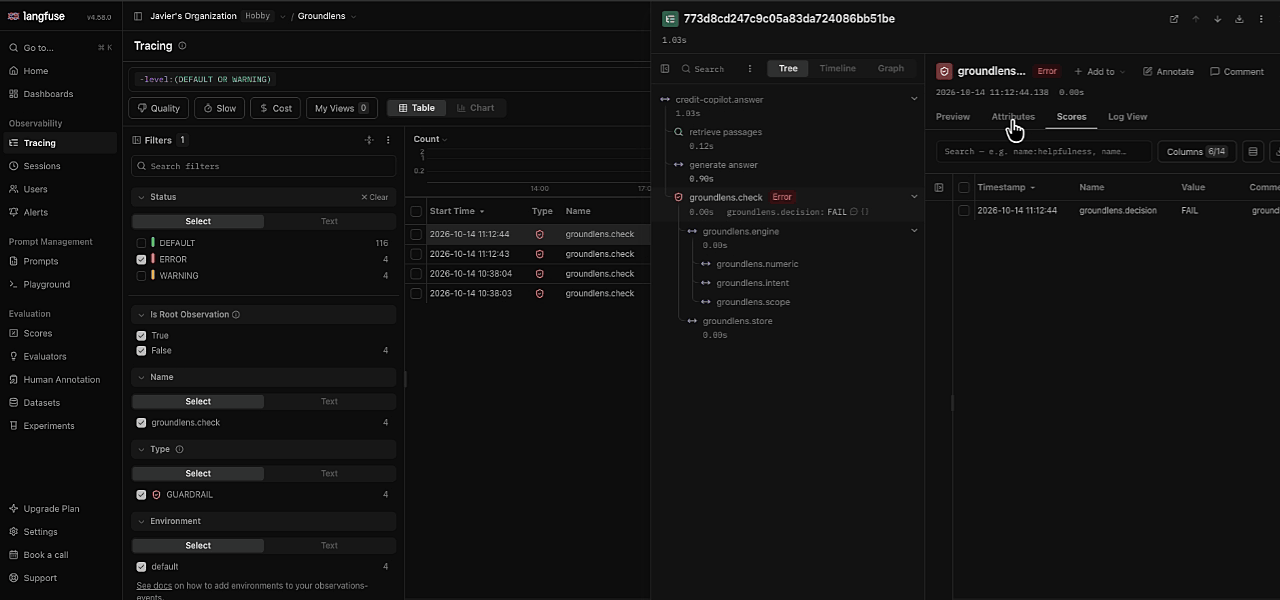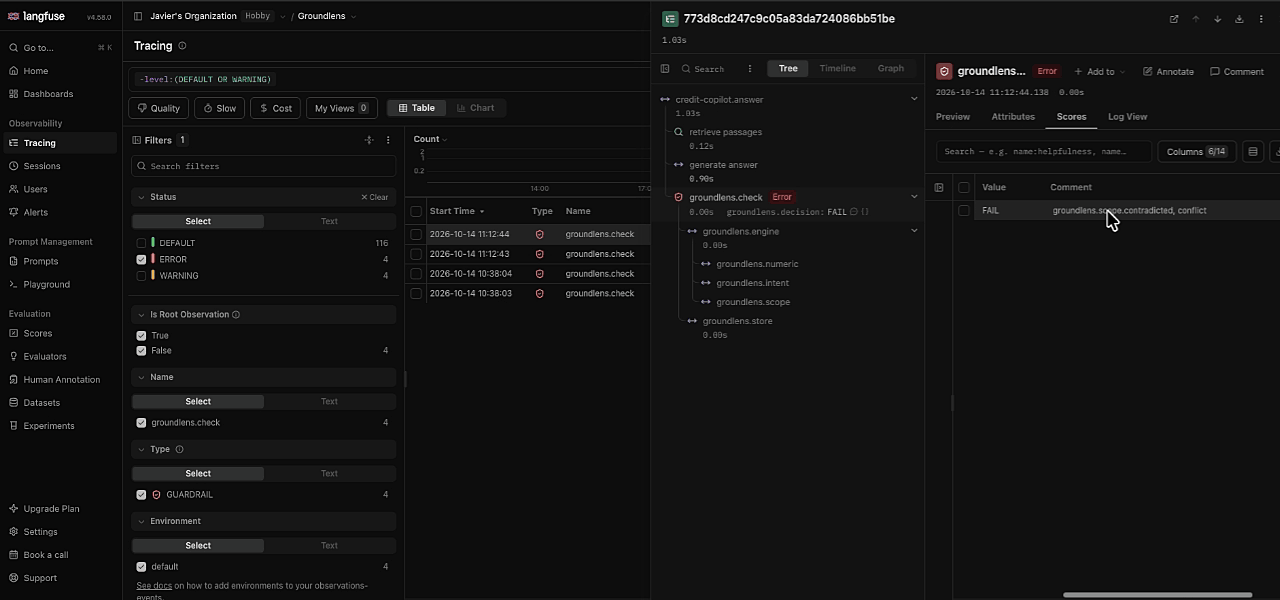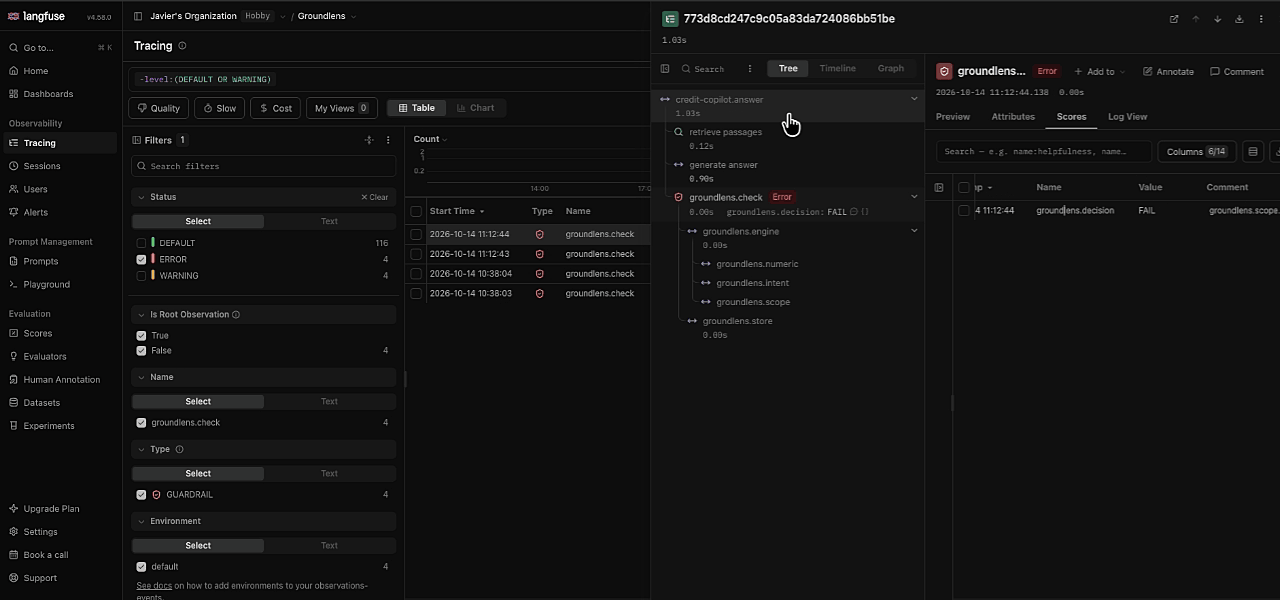
Call check inside the observation that produced the answer, and its trace gets:
- Score
groundlens.decision: categorical,PASS,REVIEWorFAIL, on the check and on its trace. Filter traces by it, chart it, export it. - Observation
groundlens.check: typeguardrail. The reasons are its status message, one per line. Its level follows Langfuse's own scale:PASSisDEFAULT,REVIEWisWARNING,FAILisERROR. - Metadata of the check: decision, reason codes (
groundlens.scope.contradicted), policy, and the id and hash of the signed record behind it. - Judge: a
generationobservation with the model name, next to your own model calls. - Spans: one per verifier, plus the store, each with its duration. Log View shows them in milliseconds.
- SDK: Python v3 and v4. Tested on Langfuse Cloud and self-hosted Langfuse 4.58.
Grafana and OpenTelemetry · pip install "groundlens[otel]"
verifier = gl.Verifier(sink=gl.sinks.jsonl("records/"), observers=[gl.integrations.otel()])Spans and metrics go through the providers your application already configured: Tempo, Prometheus, or any OpenTelemetry backend.
-
Metrics:
groundlens_decisions_total{decision, policy},groundlens_reasons_total{reason, decision},groundlens_check_duration_seconds{stage}with stagetotal,engine,judge,sign,store. -
Spans:
groundlens.checkwithgroundlens.decision,groundlens.reasons, record id and hash; children per verifier, the judge (gen_ai.*) and the store. -
Dashboard: the one in the image.
gl.integrations.grafana_dashboard()returns the path of its JSON; import it in Dashboards → New → Import. -
PromQL, share of answers that failed:
sum(rate(groundlens_decisions_total{decision="FAIL"}[15m])) / sum(rate(groundlens_decisions_total[15m])) -
Alert when more than 5 % fail:
- alert: GroundLensFailRateHigh
  expr: sum(rate(groundlens_decisions_total{decision="FAIL"}[15m])) / sum(rate(groundlens_decisions_total[15m])) > 0.05
  for: 10m
-
Try it:
docker run -p 3000:3000 -p 4318:4318 grafana/otel-lgtm, thenpython examples/observability/credit_copilot.py grafana --minutes 5. Tested on Grafana 12 with Tempo and Prometheus.
Claude, Codex, Cursor, VS Code and other MCP clients · uvx --from "groundlens[mcp]" groundlens mcp
Your assistant checks its own draft before it answers. Three read-only tools over stdio: verify_answer, verify_run, verify_records. Needs uv.
-
Claude Code (plugin: the MCP server plus a skill that tells Claude when to check):
claude plugin marketplace add groundlens-dev/groundlens
claude plugin install groundlens@groundlens
-
Codex:
codex mcp add groundlens -- uvx --from "groundlens[mcp]" groundlens mcp -
Any MCP client (Claude Desktop, Windsurf, Zed...):
{ "mcpServers": { "groundlens": { "command": "uvx", "args": ["--from", "groundlens[mcp]", "groundlens", "mcp"] } } }With the package installed (
pip install "groundlens[mcp]"),"command": "groundlens-mcp"is enough. -
Nothing to install: the Hugging Face Space is also a remote MCP server, with
verify_answer, athttps://groundlens-groundlens.hf.space/gradio_api/mcp/.
OpenClaw · clawhub install groundlens
A skill on ClawHub, the skill registry of OpenClaw. Before your assistant sends an answer with figures taken from your documents, it runs groundlens verify on its draft:
- PASS: the answer goes out.
- FAIL: it fixes the figure from the source and checks again.
- REVIEW: the answer goes out, saying which figure it could not confirm.
Runs on your machine, with no API key and no second model. The skill is in plugins/groundlens/skills/groundlens, the same one the Claude Code plugin uses. OpenClaw can also use the MCP server directly, with openclaw mcp add.
Where records are kept · sink=
check() returns only after the signed record is stored. If it cannot be stored, check() raises and no decision comes back. Each sink keeps a chain: every record carries the hash of the one before it.
| Sink | What you pass | How it stays append-only |
|---|---|---|
gl.sinks.jsonl("records/") |
a directory or a .jsonl path |
one JSON line per record, flushed to disk and locked on every write. For development and single machines |
gl.sinks.s3_object_lock(boto3.client("s3"), "bucket") |
your S3 client and a bucket created with Object Lock | one object per record, written only if absent; retain_days= adds a retention date (COMPLIANCE mode by default) |
gl.sinks.azure_blob(container_client) |
an azure.storage.blob.ContainerClient |
one blob per record, never overwritten; give the container a time-based immutability policy |
gl.sinks.postgres(psycopg.connect(...)) |
any DB-API connection | one row per record; the table is created if missing, and its keys stop a position from being written twice or a chain from forking |
import boto3
verifier = gl.Verifier(
    signer=gl.signers.aws_kms(boto3.client("kms"), key_id),           # the key never leaves KMS
    sink=gl.sinks.s3_object_lock(boto3.client("s3"), "audit-records", retain_days=3650),
)
Several processes: give each its own chain (chain="worker-3") and verify them together with groundlens record verify. GroundLens depends on none of these SDKs: you pass the client you already use. Postgres, S3 Object Lock, AWS KMS, Azure Blob and PKCS#11 are tested in CI against real software (Postgres, MinIO, LocalStack, Azurite, SoftHSM); Azure Key Vault has no emulator and is experimental.
The exact checks catch a figure that is wrong, miscalculated, from another company or of another kind than asked. They cannot catch a real figure taken from the wrong row of the right table, or a sentence the passages never say. For that you connect a model that reads: the judge. GroundLens ships no model; you pass the client you already use.
from openai import OpenAI

verifier = gl.Verifier(
    "credit_desk.yaml",                                       # a policy that allows a judge, below
    judge=gl.judges.openai_compatible(OpenAI(), "gpt-4.1"),
    sink=gl.sinks.jsonl("records/"),
)| Adapter | Client |
|---|---|
gl.judges.openai_compatible(client, model) |
openai.OpenAI, or any server with the same API: vLLM, Ollama, your gateway (base_url=) |
gl.judges.azure_openai(client, deployment) |
openai.AzureOpenAI |
gl.judges.bedrock(client, model_id) |
boto3.client("bedrock-runtime") |
The shipped policies forbid a judge, so the policy that uses one says so:
id: credit_desk
version: 1.0.0
extends: eu_ai_act_high_risk_v1
verifiers:
  forbidden: []          # allow llm_judge.*
judge:
  required: true         # no judge, or a judge that fails: REVIEW
  contradicted: REVIEW   # or FAIL
  unsupported: REVIEW
The judge can escalate, never pass. It labels each sentence supported, unsupported, contradicted or uncertain. supported resolves nothing on its own, so a judge that is wrong, or that a passage has talked into agreeing, cannot let through an answer the exact checks fail. A timeout, an error or a malformed reply is REVIEW.
You see exactly what it is sent. One prompt per answer, from a fixed template (groundlens.judge/1): what PASS means for you, the scope, the question, the answer and every passage with its provenance. Passages sit between markers they cannot contain, so text inside them is data, not instructions. groundlens judge show-template prints the exact prompt before anything is sent anywhere.
The record keeps the trail. The template id, the hash of the prompt, the model the provider says answered and the hash of its reply, with each sentence's label, the passages it cited and its one-line reason. In Langfuse the judge appears as a generation, next to your own model calls.
GroundLens splits verification into five parts that never mix: claims, verifiers, evidence, policy and record.
- The answer is cut into claims: each figure and each sentence, with its character offsets.
- Verifiers examine each claim against the passages and return evidence (
supported,contradicted,unsupported), never a verdict. The shipped ones are exact: numeric (exact fractions, locales, units, recomputed sums and ratios), scope, intent, and your rules. The judge, if you connect one, is the model you already use, asked through a fixed template. - The evidence graph keeps what each verifier said about each claim, and where they disagree.
- The policy, a YAML file you own, turns evidence into a decision:
PASS,REVIEWorFAIL, with reasons. - The record holds the input hash, the evidence, the policy hash and the decision, chained to the previous record and signed. It is stored before
checkreturns; observers are told after.
The engine is Rust, shipped as a Python wheel (abi3, Python 3.10+), with a standalone glv binary that checks records without Python. It runs in your process: no server, no network, no runtime dependencies. From Rust, cargo add groundlens; for the binary, cargo install groundlens-cli.
Parameter of Verifier |
Options |
|---|---|
policy |
groundlens_default_v1 (default), eu_ai_act_high_risk_v1, or your YAML, which can extends either |
signer |
local_key (development), aws_kms, azure_key_vault, pkcs11 |
sink |
jsonl, s3_object_lock, azure_blob, postgres |
judge |
openai_compatible (OpenAI, vLLM, Ollama…), azure_openai, bedrock; optional |
observers |
integrations.langfuse, integrations.otel, or your own |
locale, rounding |
how numbers are read and compared |
Parameter of check |
|
|---|---|
answer, passages |
required; passages as strings or (id, text, provenance) |
question |
enables the intent check: the answer gives the kind and unit asked for |
scope |
what the request is about ({"entity": "ACME"}): a figure from another entity fails |
risk_class |
a class your policy can send to human review whatever the checks say |
The checks produce evidence. The policy decides what that evidence means for you: what fails, what goes to a person, and what PASS allows. It is a short YAML file that you own and version with your code. The same answer under two policies can get two different decisions, and both are correct; that difference is your risk appetite, written down.
Two policies ship with GroundLens:
| Policy | For |
|---|---|
groundlens_default_v1 (default) |
any application. A contradicted figure or a figure from outside the scope fails; an answer of the wrong kind or unit goes to review. No model decides. |
eu_ai_act_high_risk_v1 |
systems under Annex III of the EU AI Act. The same rules, with each decision mapped to Art. 15(1) accuracy, Art. 14(4)(a) human oversight and Art. 12(1) record keeping. |
Extend a shipped policy and write only what differs:
id: credit_desk
version: 1.2.0
extends: eu_ai_act_high_risk_v1
pass_means: "may be shown to the analyst as a summary of the filing"
locale: es-ES                     # how the documents write numbers: 1.234,56
rounding: half_even               # how a recomputed figure may round
scope:
  required: [entity]              # every request must name the borrower
  missing_scope: REVIEW           # or FAIL; never PASS
risk_classes:
  default: credit_information
  mandatory_review: [credit_limit_change]   # always seen by a person
verifier = gl.Verifier("policies/credit_desk.yaml")
verifier.check(answer=a, passages=p, scope={"entity": "Talleres Norte"}, risk_class="credit_limit_change")| Key | What it sets |
|---|---|
extends |
a shipped policy to start from. Maps merge key by key, lists replace. Your policy must set its own id and version. |
pass_means |
what PASS allows in your application, in one sentence. A verifier's PASS is not a decision to publish; this says which one it is. |
locale, rounding |
how figures are read and compared: half_up, half_even or within_last_digit. Written here, they win over the request. |
scope |
the keys every request must carry, and what a missing one gets. |
risk_classes |
classes that always go to review. A class the policy does not list is an error, so a typo cannot route around review. |
verifiers |
which checks are required, recommended, optional, fallback or forbidden. |
decision |
which verifiers can fail an answer, which send it to review, and what unresolved or conflicting claims get. |
judge |
whether a judge is required and what its labels may do. See LLM-as-a-judge. |
regulatory_mapping |
which control and article each decision evidences, in your own control ids. |
Unknown keys are errors, not ignored: a misspelt rule never silently does nothing.
| Situation | Decision |
|---|---|
| a figure contradicts the passages, under the rounding rule | FAIL |
| a figure comes only from a passage outside the scope | FAIL |
| a required scope key is missing | REVIEW (or FAIL, if the policy says so) |
| a risk class that requires review | REVIEW, whatever the checks say |
| a check could not run, or the judge timed out or failed | REVIEW |
| the record cannot be stored | an exception, and no decision |
The final decision is the worst outcome of all checks.
groundlens policy lint policies/credit_desk.yaml                # errors before you deploy
groundlens policy show --resolved policies/credit_desk.yaml     # every default filled in
The hash of the resolved policy goes into every record it decides, so each decision can be traced to the exact rules that produced it.
Before you change a policy,you have to measure it:
groundlens measureestimates the share of wrong answers among those that passed, from a small sample your team labels without seeing the verdicts, with a 95 % confidence interval, per risk class, and the cost per decision.groundlens replayruns past traffic under the new policy and lists the decisions that would change.
Both reports are signed. Full reference: Writing policies.
GroundLens sits on the path between a model and a decision, and its records are meant to be evidence. Both make it a target: an attacker may try to get a wrong answer through, or to alter the trail afterwards.
| Threat | Control |
|---|---|
| A wrong answer passes | Exact checks with no model in the default path; errors and timeouts are REVIEW, never PASS; no stored record, no decision |
| Instructions hidden in passages steer the judge | Passages are delimited data in a fixed, versioned template; the judge can only escalate; adversarial tests |
| A record is edited, deleted or reordered | SHA-256 content hash, hash chain, signature; groundlens record verify checks offline with the public key alone |
| The signing key leaks | Keys stay in AWS KMS, Azure Key Vault or a PKCS#11 HSM (ECDSA P-256); GroundLens never holds them |
| Two writers fork a chain | Conditional writes in every sink; a lost race is retried, never overwritten |
| Data leaves through the verifier | No network code in the engine (cargo-deny bans HTTP and TLS crates); other systems are reached only through clients you pass in |
| Hostile input exhausts the parser | Bounded numeral grammar against regular-expression DoS; fuzzing of every parser |
| A tampered release | Pinned and hashed CI dependencies, SLSA Build Level 3 provenance, signed release binaries, OpenSSF Scorecard |
Report vulnerabilities privately through GitHub security advisories. See SECURITY.md.
If GroundLens got one of your answers wrong, that case is the most valuable contribution there is. Checks, connectors and documentation are welcome too; CONTRIBUTING.md explains how to start.
Apache-2.0, all of it: engine, checks, policies, connectors, command line and MCP server. Verification evidence has to be checkable by anyone, without our software or our permission, and that only holds if the verifier is open.
You can contact the developer at javier@groundlens.dev
1. GroundLens 6.0.5, default policy, no judge. Financial answers: 189 real answers by Claude Haiku from a RAG over FinQA 10-K pages (e5 embeddings, top 4 passages), on multi-step questions never used while developing GroundLens. Each answer labelled twice by a language model (Claude Opus 5.5, claude-opus-5-5) against fixed written criteria, blind to GroundLens, with a third pass on the 3 disagreements; labels were frozen before GroundLens ran. 22 answers were wrong (1 in 9): 17 got FAIL or REVIEW (77 %, 95 % CI 57–90 %). Of the 129 answers that passed, 5 were wrong (3.9 %, 95 % CI 1.7–8.8 %). The price: 60 of 189 answers (32 %) went to FAIL or REVIEW, including 38 of 110 correct ones. Median 10.6 ms per check in a fresh process. Public claims: LLM-AggreFact test split (29,320 claim–document pairs from 11 sets, human labels), never used while developing GroundLens. Of the 1,616 unsupported claims that contain a number, 796 got FAIL or REVIEW (49 %, 95 % CI 47–52 %); among the claims with a number that passed, 16.3 % were unsupported, against 25.4 % before the check. Claims without a number all passed: GroundLens caught none of their errors. Median 4.0 ms per check. All results, including the sets where it does not help, in BENCHMARK.md.
Copyright Groundlens 2026