Cut LLM costs per PR. Downshift finds every LLM call in a Python repo, tests cheaper models against evals written for each call site, recommends the safe downgrades, and shows the projected cost impact of every pull request.



Live demo: downshift-llm.vercel.app | Demo video: 2-minute walkthrough
Downshift is the toolkit, IBM Bob is the brain. Static analysis gets most of the way. Bob closes the gaps that need real code understanding (models and prompts only known at runtime, one helper serving several features), writes the evals, applies the changes, and reviews PRs. Everything except the audit runs without Bob.
pip install downshift
curl -O https://raw.githubusercontent.com/ana-lan/downshift/main/downshift.example.yaml
downshift scan path/to/repo
downshift estimate path/to/repo/.downshift/callsites.json -c downshift.example.yaml
scan lists every LLM call site with its model, prompt and output type. estimate prices them per month with the prices and volumes in the config. Edit both to match your provider and traffic.
downshift scan path/to/repo                                     # 1. find call sites
downshift evalgen --callsites path/to/repo/.downshift/callsites.json \
  --out path/to/repo/.downshift/evals                           # 2. write evals (or use Bob)
downshift run --callsites path/to/repo/.downshift/callsites.json      # 3. baseline vs cheaper models
downshift report --callsites path/to/repo/.downshift/callsites.json \
  --out report.md                                               # 4. decision per call site
downshift diff path/to/repo --base main # 5. cost change of your branch| Command | What it does |
|---|---|
scan |
Find every LLM call site in a repository. |
validate |
Check a callsites or audit file against the schema. |
compare |
Compare the ast scan with a Bob audit, side by side. |
check-evals |
Check eval files against the call sites they test. |
evalgen |
Generate an eval set for each call site with a configured model. |
run |
Run each call site's evals on the baseline and candidate models, and score them. |
rescore |
Re-grade saved outputs of judge-graded call sites with the configured judge. |
report |
Render the cost and quality report. |
estimate |
Project monthly LLM cost from a scan or audit file. No evals needed. |
diff |
Show the projected LLM cost change between two git refs. |
export |
Export JSON and the report for the demo web app. |
repo ──► scan (ast) ──► Bob audit ──► evals ──► run ──► decide ──► report
          static         runtime       per       base +   cheapest    cost +
          analysis       models,       call      cheaper  model that  quality
                         shared        site      models   keeps the   per site
                         helpers                          quality bar
PR   ──► diff (base vs head) ──► GitHub Action comment: "+$X/month"
- Scan. An AST scanner finds OpenAI (v1 SDK) and Anthropic calls. It resolves models through constants, imports, env var defaults, dict lookups and parameter defaults, recovers prompt templates, and records callers.
- Audit (Bob). The Downshift Auditor mode reads only the call sites the scanner could not resolve, splits shared helpers into the features they serve, and adds purpose, output contract, difficulty and grading. Output is checked with
downshift validate. - Evals. 20 to 25 cases per call site, graded by exact match, JSON fields, or an LLM judge.
- Run and decide. Each call site runs on the baseline and every cheaper candidate. A candidate wins if it keeps
quality_thresholdof the baseline's quality and passesmin_pass_rateof cases. The cheapest winner is recommended. - Report and diff. Monthly cost before and after, per call site, from real token counts, your prices and your volumes.
diffprojects the change a branch makes, and the GitHub Action posts it on every PR.
SupportDesk (examples/supportdesk) is a synthetic support ticket app with 8 LLM features, 40 synthetic tickets and a refund policy document.
| ast scan | Bob audit | |
|---|---|---|
| Call sites / features | 7 | 8 |
| Models resolved | 6 | 8 |
| Prompts resolved | 5 | 8 |
After evals on local Qwen 2.5 models (7b baseline; 3b, 1.5b, 0.5b candidates), 3 of 8 call sites can downgrade. Projected monthly cost goes from $3,137.26 to $2,572.61, saving $564.65 (18%), while the mean pass rate moves from 68.3% to 68.9%. Full report: examples/supportdesk/downshift.report.md. Bob then applied the decisions and opened the PR itself.
| Repo | License | ast scan | Bob audit | Projected monthly cost |
|---|---|---|---|---|
| OrchestrAI | MIT | 1 site, 0 models | 5 features, 5/5 models, 5/5 prompts | $540 static-only vs $2,409 with Bob (about 4.5x) |
| mem0 | Apache-2.0 | 14 sites, 1 model | 4 real features on the default path, all resolved | $307 static-only vs $2,330 with Bob (about 7.6x) |
In both repos, one shared helper hid most of the spend from static analysis. In mem0, Bob found that the reranker makes one LLM call per candidate document, about 29% of the projected bill. Both audits cost under 4 Bobcoins. See them on the web: https://downshift-llm.vercel.app/case-study/
Add a projected cost comment to every pull request:
name: LLM cost diff
on: pull_request

permissions:
  contents: read
  pull-requests: write
  issues: write

jobs:
  cost-diff:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v5
      - uses: ana-lan/downshift@v0.1.1
        with:
          path: .              # directory to scan
          fail-above: "500"    # optional: fail if the monthly increase is above $500
Inputs: path, base (default: the PR base branch), config (default: downshift.yaml in path), fail-above, comment, package, python-version, github-token.
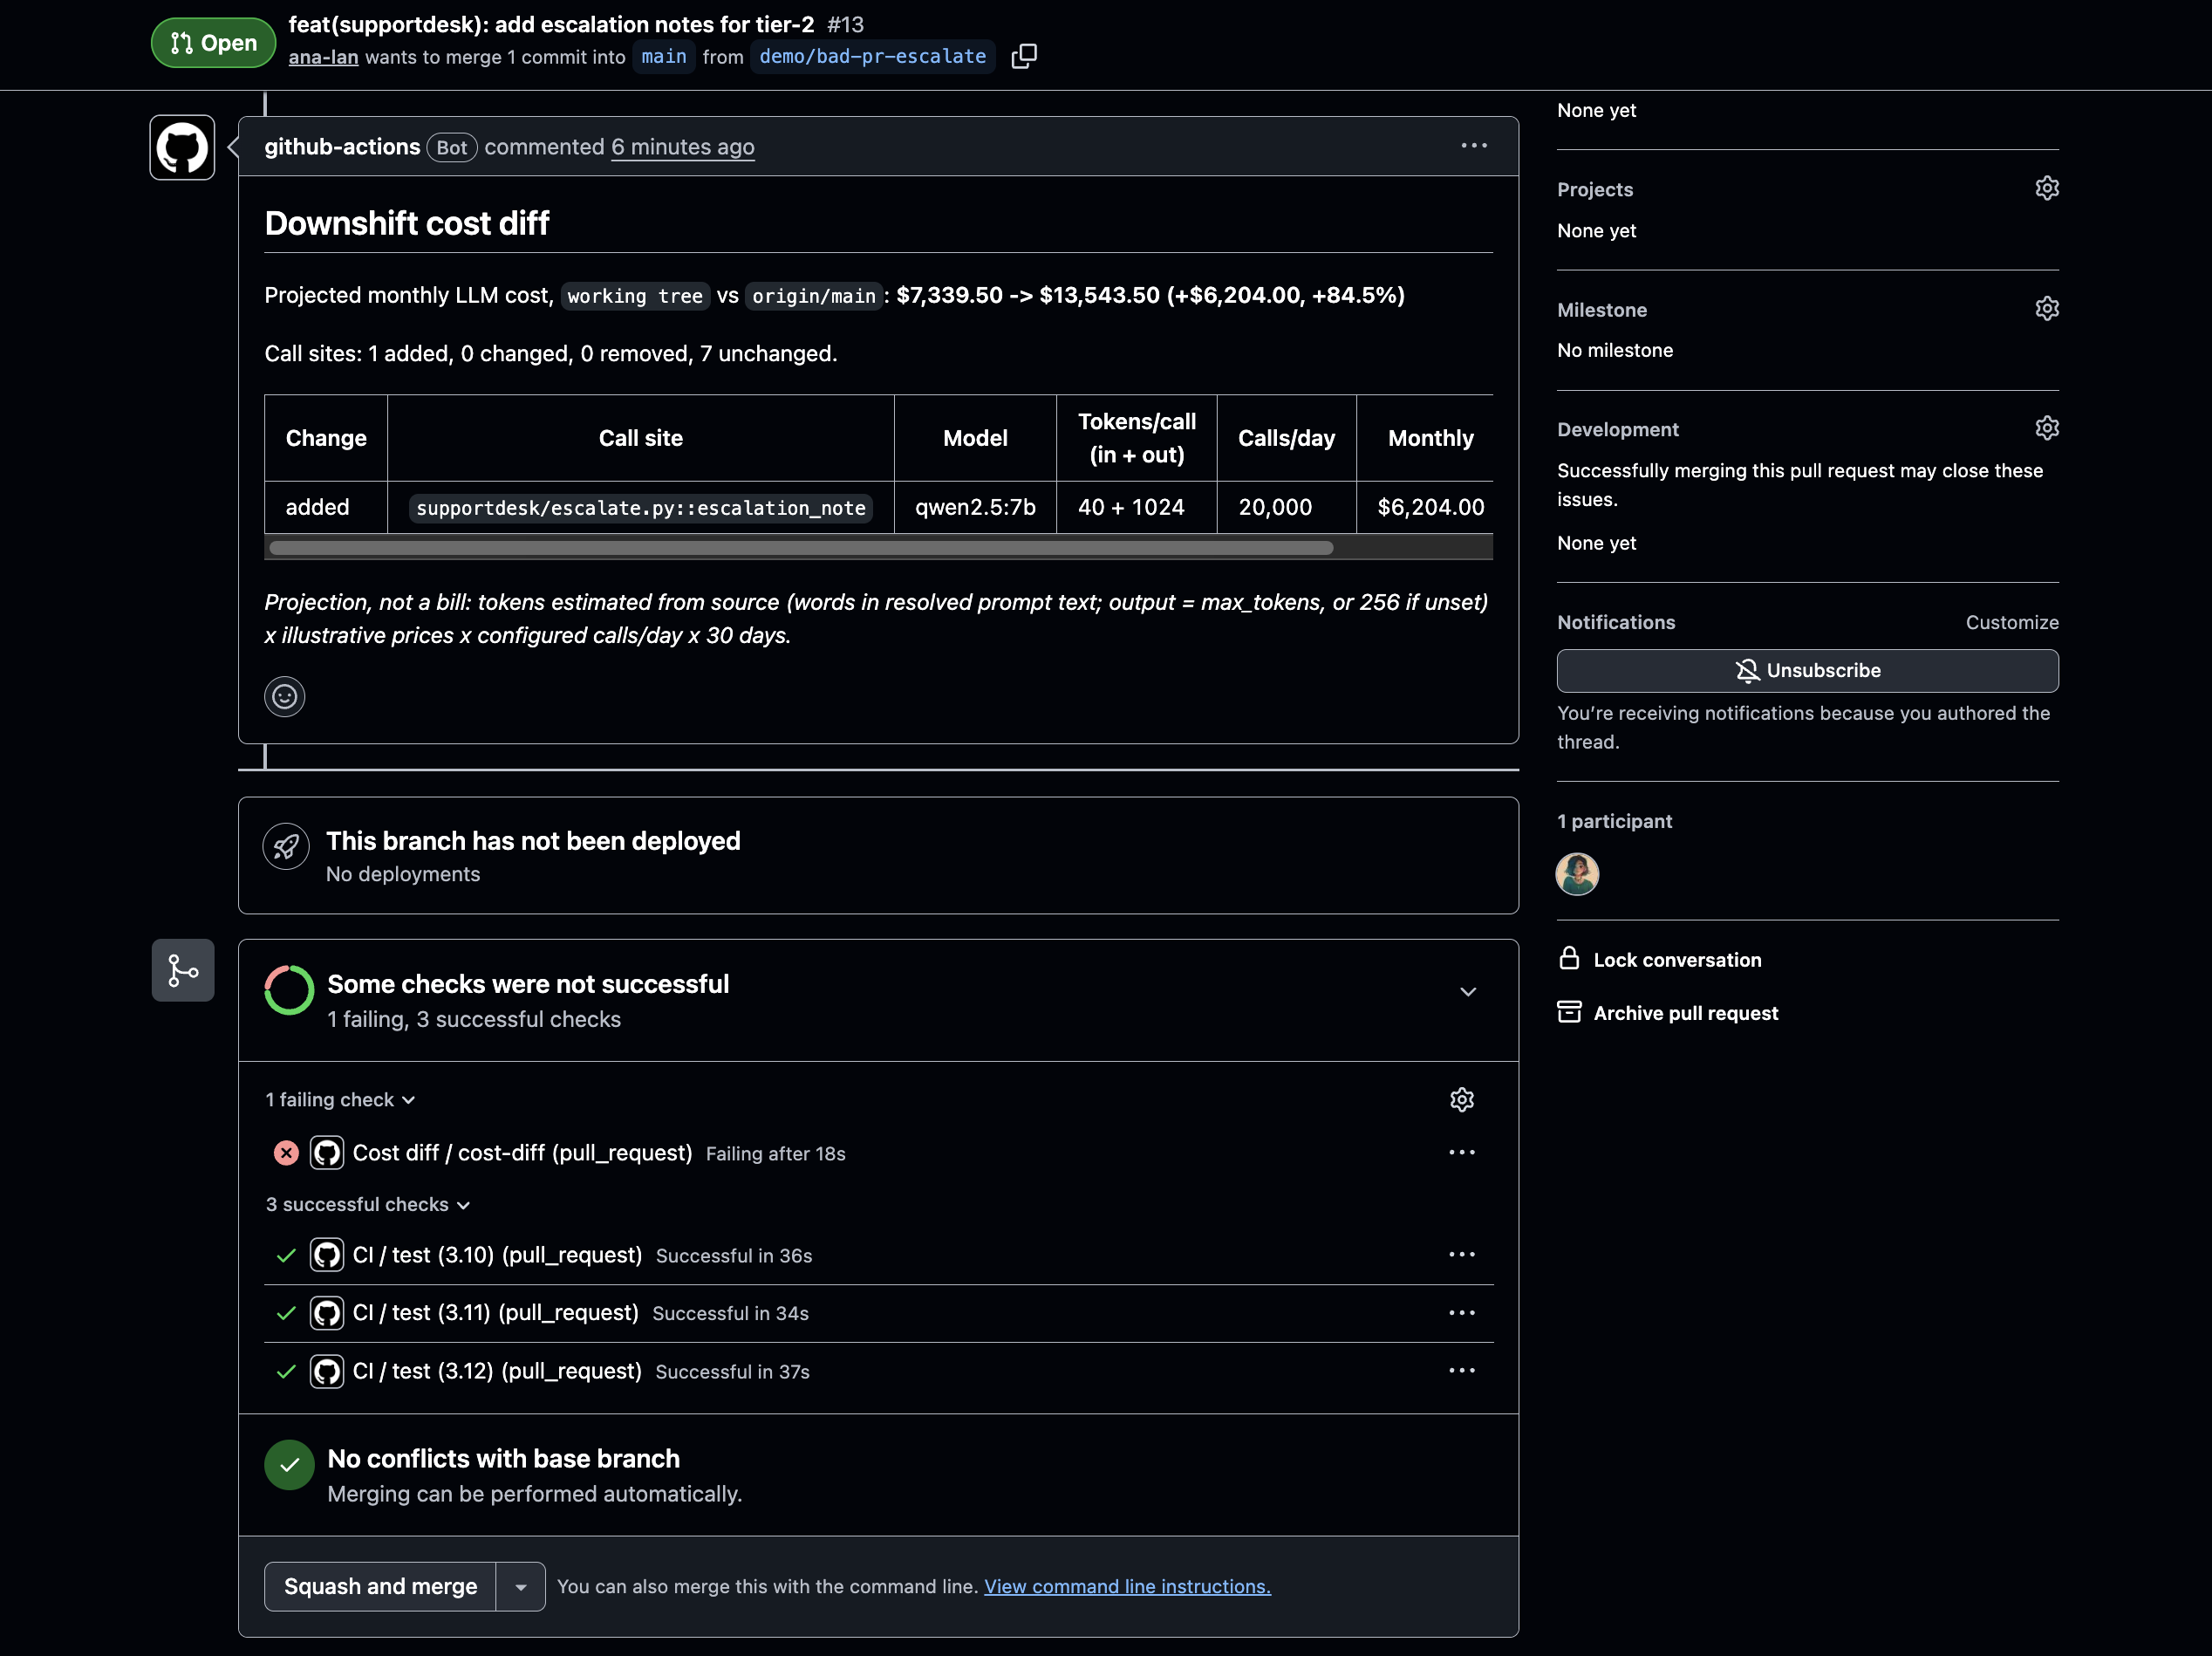
downshift.yaml sits next to the code you scan. Start from downshift.example.yaml.
version: 1
provider:
  base_url: "http://localhost:11434/v1"   # any OpenAI-compatible endpoint
  api_key_env: null                       # env var holding the key, or null
models:
  baseline: "qwen2.5:7b"
  candidates: ["qwen2.5:3b", "qwen2.5:1.5b", "qwen2.5:0.5b"]
  judge: null                             # defaults to the baseline
quality_threshold: 0.95
min_pass_rate: 0.80
pricing:                                  # USD per 1M tokens
  "qwen2.5:7b":   { input: 2.50, output: 10.00, tier: premium }
  "qwen2.5:3b":   { input: 0.40, output: 1.60,  tier: standard }
  "qwen2.5:1.5b": { input: 0.15, output: 0.60,  tier: budget }
  "qwen2.5:0.5b": { input: 0.10, output: 0.40,  tier: nano }
volume:
  default_per_day: 20000
  per_call_site: {}                       # e.g. "app/triage.py::classify": 50000
scan:
  include: ["*.py"]
exclude: ["tests/*"]The .bob/ folder ships two custom modes (Downshift Auditor, Downshift Eval Writer) and their skills. The auditor can only edit the audit file, never your code. Setup and prompts: docs/bob.md. Every Bob task in this project has a screenshot in bob_sessions/. In total, 17 tasks used 34.20 of 40 Bobcoins.
- Dollar figures are projections: real token counts x prices x assumed volume, all from your config. The demo uses illustrative prices; the case studies use list prices.
diffandestimateare static. Unresolved models are priced as the baseline, and missingmax_tokensassumes 256 output tokens. Use them for per-PR deltas, not absolute spend.- Python only. Detects the OpenAI v1 SDK and Anthropic messages API. Pre-v1
openai.ChatCompletion.create, LiteLLM and LangChain are not detected yet. - The demo runs local Qwen 2.5 models on a laptop, not a production API benchmark. Eval inputs are synthetic.
burnrate audits LLM calls with the AST and swaps models. Downshift adds per-call-site evals that prove quality holds, a per-PR cost diff in CI, and a Bob auditor for what static analysis cannot see.
git clone https://github.com/ana-lan/downshift && cd downshift
python -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
ruff format . && ruff check . && mypy src
python -m pytest            # 612 tests, no network, no models
python -m pytest -m integration   # needs a local Ollama
The web demo lives in web/ (Next.js, static export). See CONTRIBUTING.md and docs/architecture.md.
MIT