


A Spring Boot starter that enforces per-user, per-tenant and per-session token and dollar budgets on Spring AI ChatClient calls. It also caps runaway tool loops, so one request can't make a hundred model calls.
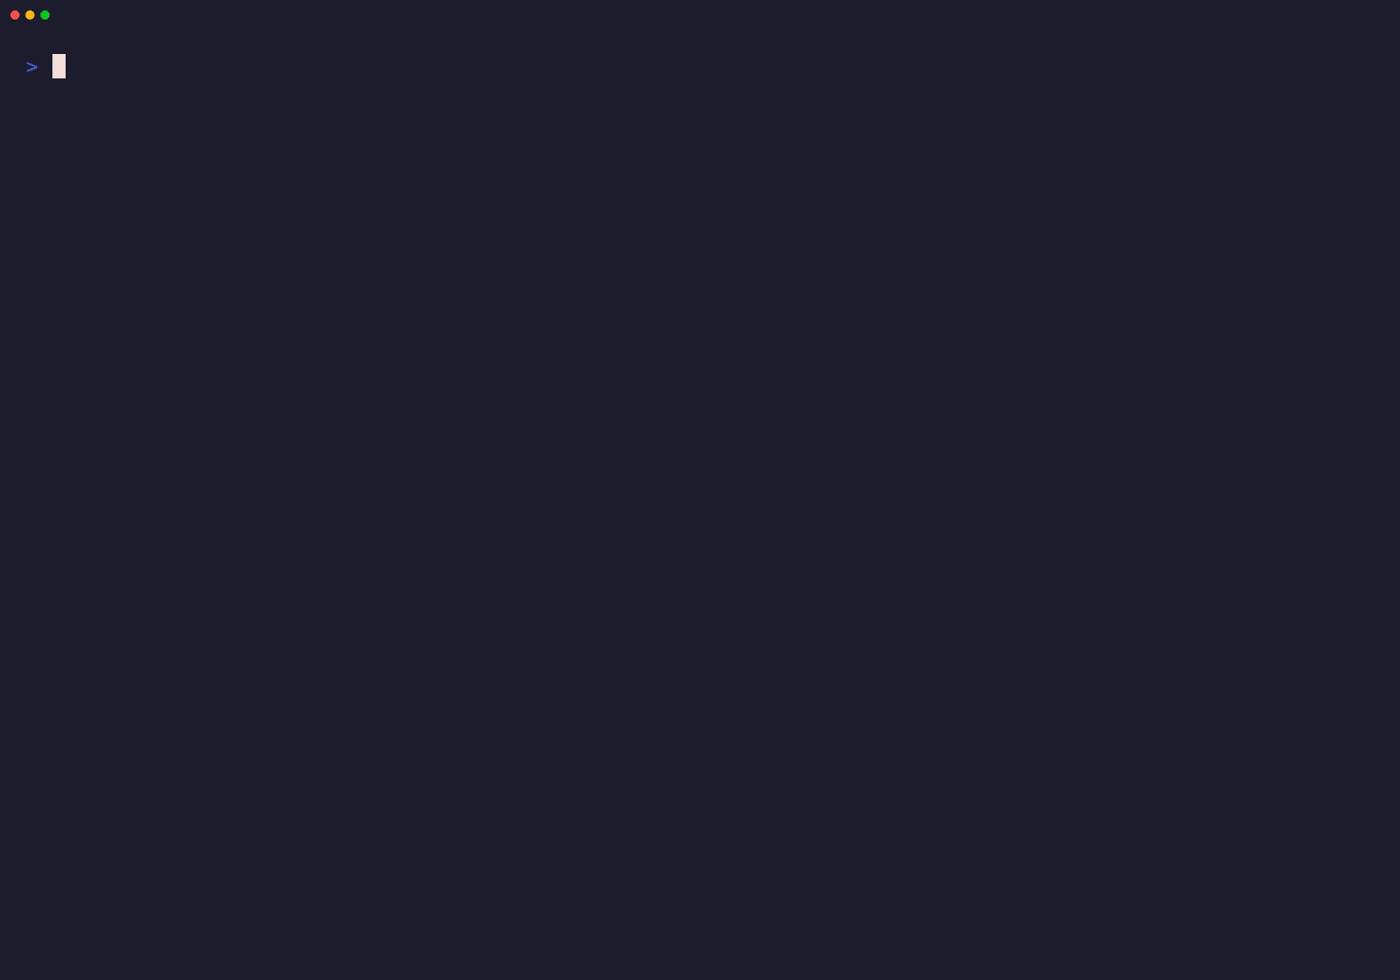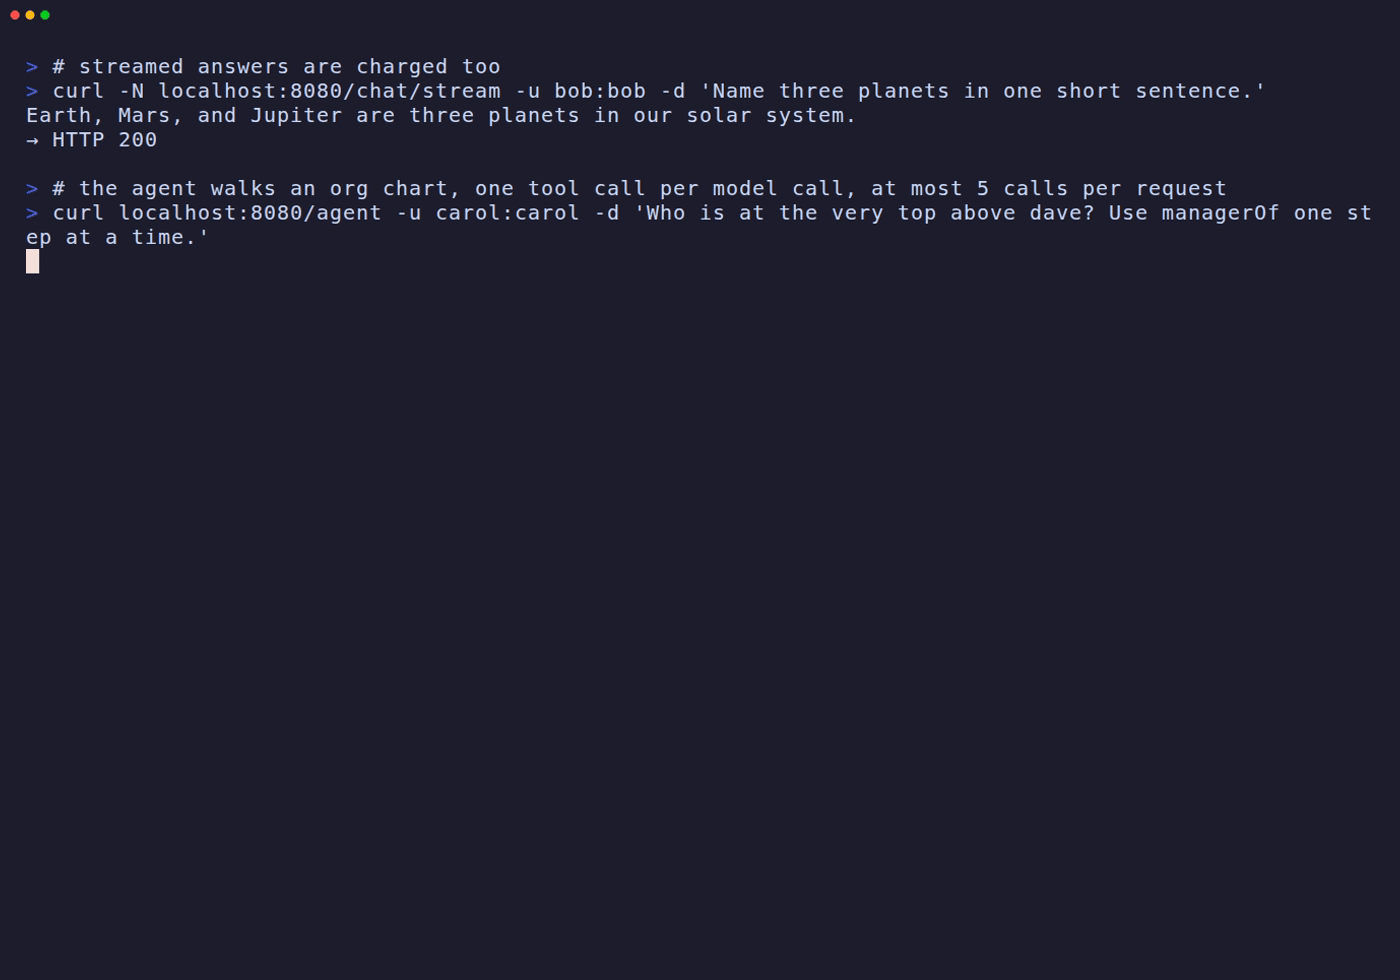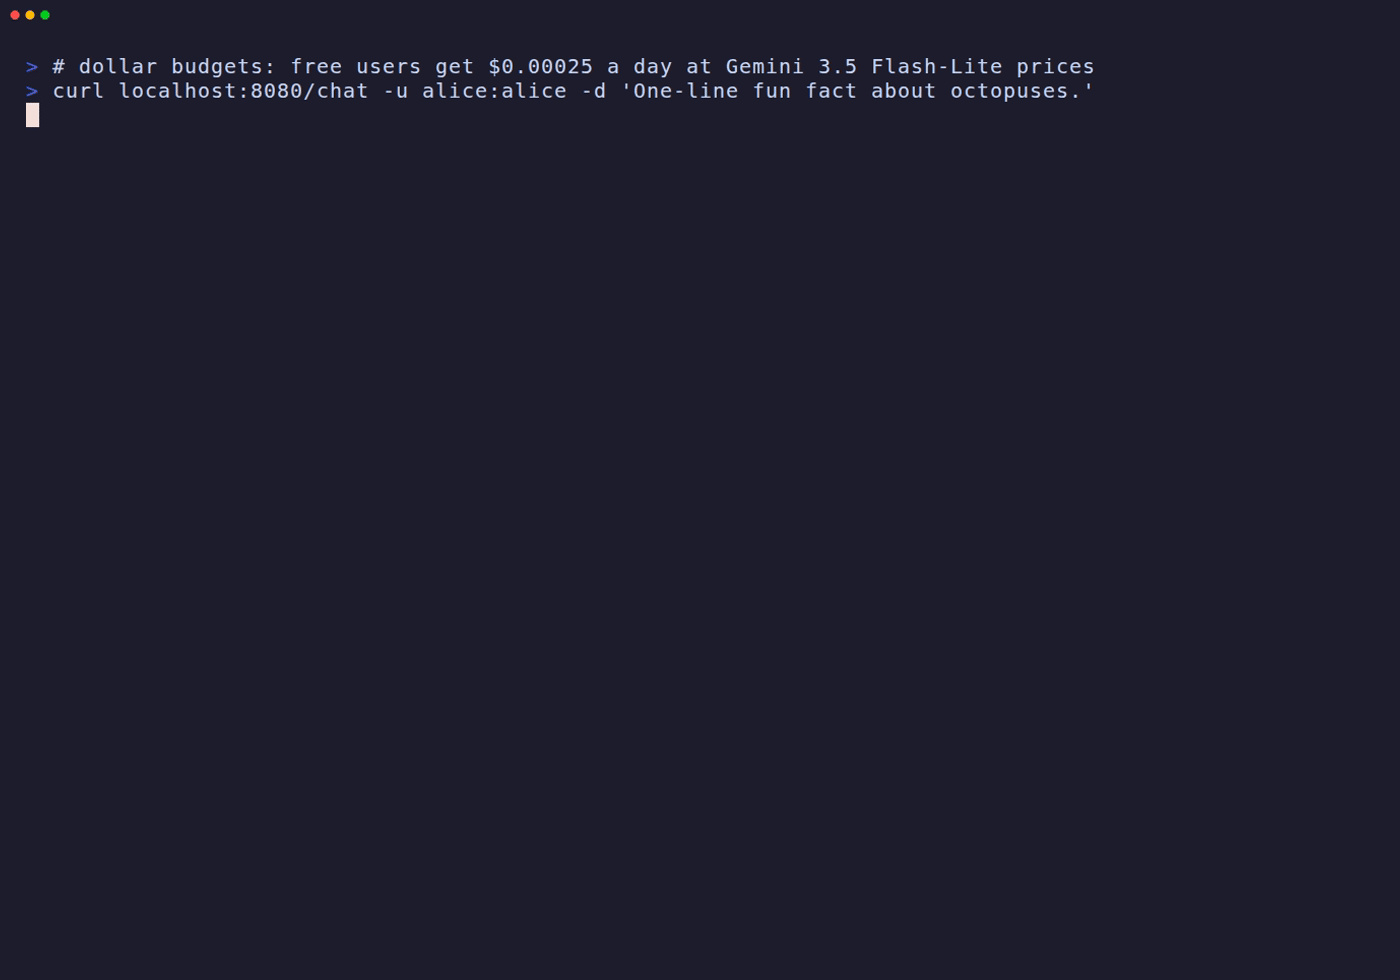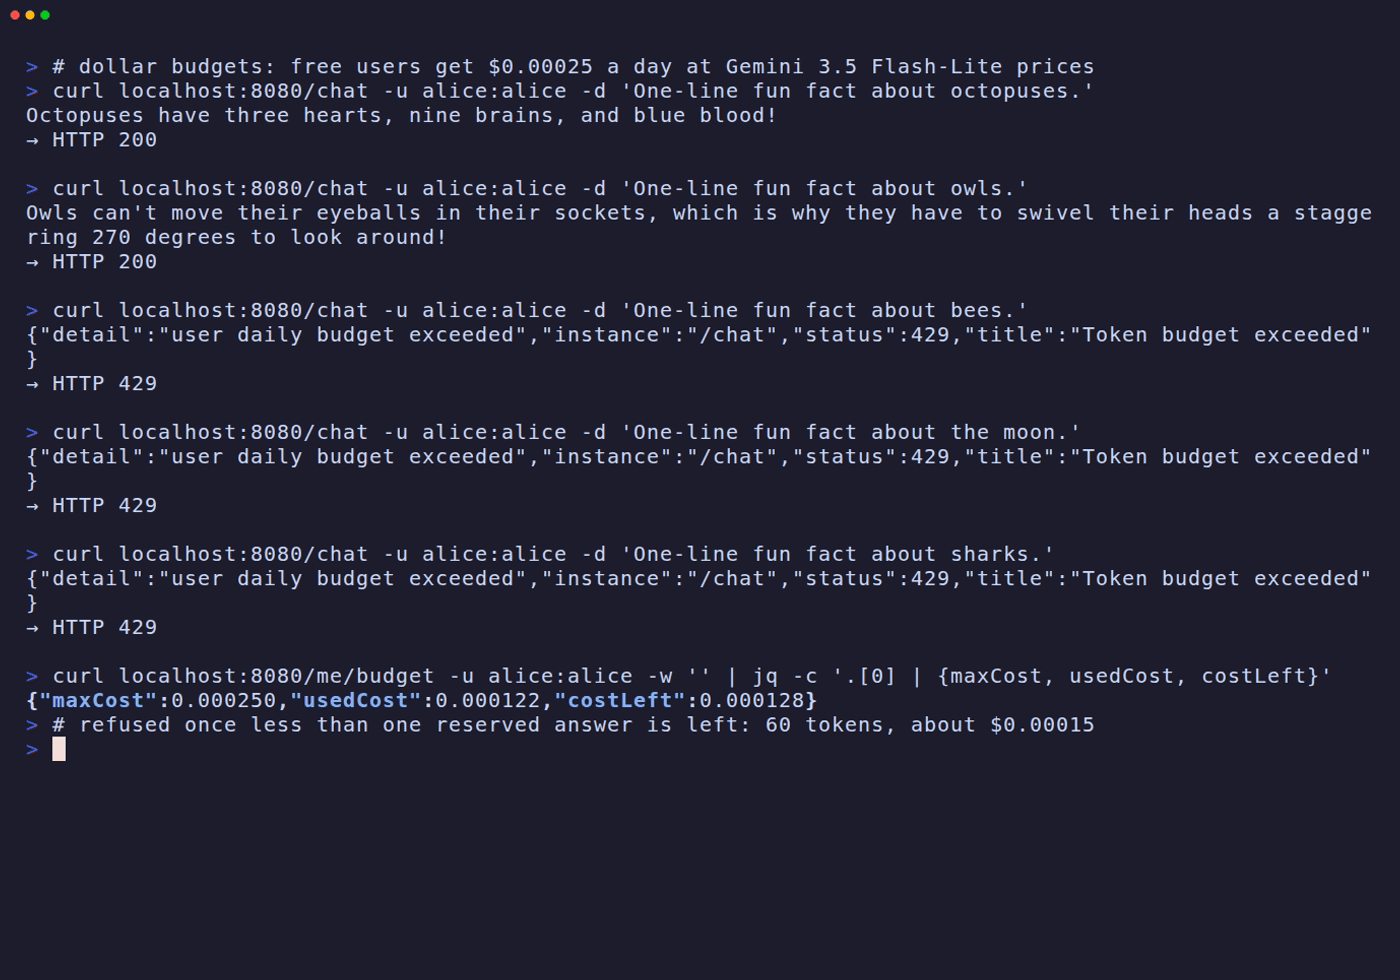
Try token-allowance-demo runs from the terminal or a small web console.
An LLM bill grows with every call, and one user, one bug or one tool loop that never ends can run it up overnight. Provider dashboards show the damage the next day. Token Allowance checks the budget before each call and charges the real usage after it, so a used-up budget is answered with 429 Too Many Requests instead of another paid call.
If you already run an LLM gateway, it can cap spend per API key or per forwarded user id. Token Allowance does it inside the app instead: there is no extra service to run, the user comes from your Spring Security login, and it sees a whole request, so it can stop a tool loop halfway.
Two advisors are added to every ChatClient.Builder that Spring AI creates:
- Admission runs once per request, before chat memory and tools. It finds who the request is for and denies it if a budget is already used up.
- Metering runs once per model call, including every round of a tool loop. It reserves an estimate before the call and replaces it with the provider's reported usage after. It also stops a request that reaches its per-request call or cost cap.
Reserving before the call means two parallel requests can't both pass a check and overspend together.
- Java 17 or later
- Spring Boot 4.1
- Spring AI 2.0, with any chat model starter (OpenAI, Anthropic, Ollama, ...)
1. Add the starter next to your Spring AI model starter:
<dependency>
    <groupId>io.github.ultron03</groupId>
    <artifactId>token-allowance-spring-boot-starter</artifactId>
    <version>0.3.1</version>
</dependency>
<dependency>
    <groupId>org.springframework.ai</groupId>
    <artifactId>spring-ai-starter-model-openai</artifactId>
</dependency>
<dependency>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-webmvc</artifactId>
</dependency>
2. Set prices and budgets in application.yml. Prices are dollars per million tokens, as on provider pricing pages; the ones below are an example.
token-allowance:
  pricing:
    models:
      - name: gpt-4o-mini
        input-per-mtok: "0.15"
        output-per-mtok: "0.60"
        cached-input-per-mtok: "0.075"
  limits:
    - { scope: user, window: daily, max-cost: "0.50" }
    - { scope: global, window: monthly, max-cost: "200.00" }
  per-request:
    max-model-calls: 10
  subject:
    header: X-User-Id   # only behind a gateway that sets it; see "Who a request is for"
3. Use the ChatClient.Builder that Spring AI gives you. Nothing else changes:
@RestController
class ChatController {

    private final ChatClient chatClient;

    ChatController(ChatClient.Builder builder) {
        this.chatClient = builder.build();
    }

    @PostMapping("/chat")
    String chat(@RequestBody String message) {
        return chatClient.prompt().user(message).call().content();
    }
}
4. Call it. Without Spring Security, the user comes from the X-User-Id header turned on above:
curl -X POST localhost:8080/chat -H 'X-User-Id: alice' -d 'Hello'When Alice's daily budget is used up, she gets:
HTTP/1.1 429 Too Many Requests
Retry-After: 41520
Content-Type: application/problem+json

{ "title": "Token budget exceeded", "status": 429, "detail": "user daily budget exceeded", "instance": "/chat" }
Retry-After is the number of seconds until the budget's window resets.
Tip: start with token-allowance.mode: observe. Nothing is blocked; a used-up budget only logs a warning. Compare the numbers with your provider's dashboard, then switch to enforce.
Budgets with scope user, tenant or session need an id. For each scope, the first of these that has one wins:
-
An advisor param on the call. This is the only way to pass tenant and session ids, and the only one that works in WebFlux, streams on other threads and background jobs. With chat memory,
ChatMemory.CONVERSATION_IDalso counts as the session id.chatClient.prompt() .user(message) .advisors(a -> a.param(SubjectParams.USER_ID, userId) .param(SubjectParams.TENANT_ID, tenantId)) .call() .content();
-
The Spring Security principal's name, if Spring Security is on the classpath. Anonymous users get no id.
-
The HTTP header named in
subject.header, only when that is set. It is off by default because a client can send any value: without a gateway that sets the header itself, a client can rotate ids to dodge per-user limits, or use up someone else's budget. Values longer than 128 characters are ignored.
A request with no id is only checked against global budgets.
Chat without a login. To give each anonymous visitor a budget, define your own resolver chain with the client's IP address last:
@Bean
SubjectResolver subjectResolver() {
    SubjectResolver byClientIp = request -> {
        if (RequestContextHolder.getRequestAttributes() instanceof ServletRequestAttributes attributes) {
            return Map.of(Scope.USER, "ip:" + attributes.getRequest().getRemoteAddr());
        }
        return Map.of();
    };
    return new CompositeSubjectResolver(List.of(new AdvisorParamSubjectResolver(),
            new SpringSecuritySubjectResolver(), byClientIp));
}
Behind a load balancer that sets X-Forwarded-For, also set server.forward-headers-strategy: framework. Everyone behind one office network then shares a budget.
limits apply to everyone; a plan lists only what differs. A plan limit replaces the common limit with the same scope and window, and any other plan limit is added:
token-allowance:
  limits:
    - { scope: user, window: daily, max-cost: "1.00" }
    - { scope: global, window: monthly, max-cost: "200.00" }
  plans:
    pro:
      - { scope: user, window: daily, max-cost: "10.00" }
      - { scope: user, window: minute, max-tokens: 20000 }
A pro user gets $10 a day, at most 20,000 tokens a minute, and shares the global $200. Plans can't set global limits.
The plan comes from the SubjectParams.PLAN advisor param, or else from a Spring Security authority named PLAN_<name> (for example PLAN_pro). Never from a header, because a client could claim any plan. A caller with no plan, or an unknown one, gets the common limits.
Spend is counted per user, not per plan: when Alice upgrades after spending $0.80 today, she has $9.20 left, not a fresh $10.
If plans change while users are logged in, or caps live in your own database, replace the limits instead:
@Bean
LimitResolver limitResolver(ContractRepository contracts) {
    return caller -> {
        String tenantId = caller.subjectIds().get(Scope.TENANT);
        if (tenantId == null) {
            return List.of();
        }
        return List.of(new Limit(Scope.TENANT, Window.MONTHLY, null, contracts.monthlyCapOf(tenantId)));
    };
}
The resolver is asked before every model call and when the call is charged, so cache slow lookups. It must return at most one limit per scope and window.
per-request.* applies to every request. An endpoint that needs a different cap, such as an agent that walks a tool loop, sets its own on its client; anything it doesn't set comes from per-request:
ChatClient agentClient = chatClientBuilder
    .defaultAdvisors(a -> a.param(RequestLimitParams.MAX_MODEL_CALLS, 20)
        .param(RequestLimitParams.MAX_REQUEST_COST, "0.50"))
.build();The BudgetService bean shows a subject's spend and lets support give some back:
List<BudgetStatus> budgets = budgetService.statusOf(Scope.USER, "alice", plan);
budgetService.topUp(Scope.USER, "alice", new Amount(0, Money.ofDollars("2.00")));
budgetService.reset(Scope.USER, "alice");
Each BudgetStatus has the limit, the spend (committed by finished calls, reserved by running ones) and when the window resets, so you can show users what they have left. topUp takes an amount off committed spend, never below zero, and reset clears it, in the current minute, hour, day and month windows. Neither has an HTTP endpoint; expose them through your own admin API if you need one.
All properties start with token-allowance.. Write amounts as strings ("0.50") so YAML doesn't turn them into floating-point numbers.
| Property | Default | Meaning |
|---|---|---|
enabled |
true |
Turns everything off when false. |
mode |
enforce |
enforce denies requests over budget; observe only logs them. |
zone |
UTC |
Time zone in which hour, day and month windows start. |
subject.header |
none | HTTP header with the user id, such as X-User-Id. Unset, no header is read. |
pricing.unknown-model |
reject |
A model with no price: reject fails a call that a cost cap applies to and counts only tokens for the rest, allow-uncosted always counts tokens only, default-price uses pricing.default-price. With only token limits, no prices are needed. |
pricing.default-price.* |
none | Price for unknown models, with the same fields as a model below. |
pricing.models[n].name |
none | Model name, matched ignoring case and a trailing date (gpt-4o-2024-08-06 uses the gpt-4o price). |
pricing.models[n].input-per-mtok |
none | Input price per million tokens. |
pricing.models[n].output-per-mtok |
none | Output price per million tokens. |
pricing.models[n].cached-input-per-mtok |
input price | Price of input tokens read from the provider's cache. |
pricing.models[n].cache-write-per-mtok |
input price | Price of input tokens written to the provider's cache. |
limits[n].scope |
none | user, tenant, session or global. |
limits[n].window |
none | minute, hour, daily or monthly. |
limits[n].max-tokens |
none | Most tokens in one window. |
limits[n].max-cost |
none | Most dollars in one window. Each limit needs max-tokens, max-cost or both. |
plans.<name>[n].* |
none | Limits for callers on plan <name>, with the same fields as limits. |
per-request.max-model-calls |
none | Most model calls one request may make, tool-loop rounds included. |
per-request.max-cost |
none | Most dollars one request may cost. |
estimate.output-tokens |
none | Answer length a call reserves before it is made, never more than the request's max tokens. Unset reserves the request's max tokens, or 1,024 without one. |
stream.interrupted |
charge-estimate |
A stream that stops before the provider reports usage, or a call that times out waiting for the answer: charge-estimate charges the estimate, release charges nothing. |
web.exception-handler |
true |
Answers a used-up budget with 429 and an unreachable budget store with 503. Turn it off to handle BudgetExceededException and LedgerUnavailableException yourself. |
store.type |
in-memory |
in-memory keeps spend in each instance; redis shares it across instances. |
store.failure-mode |
auto |
New calls while Redis can't be reached: fail-open, fail-closed, or auto (open in observe mode, closed in enforce mode). |
thresholds |
80,100 |
Percents of each limit at which a BudgetThresholdReached event is published. |
The app fails at startup on an invalid setting, such as a price with more than six decimal places. That is almost always a per-token price where a per-million price was meant.
To keep spend in Redis, so every instance counts against the same budgets, add the Redis module and Spring Boot's Redis starter:
<dependency>
    <groupId>io.github.ultron03</groupId>
    <artifactId>token-allowance-redis</artifactId>
    <version>0.3.1</version>
</dependency>
<dependency>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-data-redis</artifactId>
</dependency>spring.data.redis:
host: localhost
timeout: 500ms # the default is 60 seconds per command
token-allowance.store.type: redisEach reserve and settle is one Lua script, so parallel calls on different instances can't overspend together. All keys share the hash tag {ta}, so on Redis Cluster they live on one node.
When Redis is down, fail-closed answers new calls with 503; fail-open lets them through unchecked and their spend is never recorded. The outage is logged once at WARN and its end at INFO. Set spring.data.redis.timeout, or every call waits up to 60 seconds before the failure mode applies. Boot's redis health indicator turns /actuator/health DOWN during an outage, even in fail-open; leave it out of your readiness group if you fail open.
With Spring Boot Actuator, or any other MeterRegistry bean:
| Meter | Type | Tags | What it counts |
|---|---|---|---|
token.allowance.decisions |
counter | stage (admission, request, reservation), outcome (allowed, denied, observed, ledger-unavailable), scope |
Every admission and reservation, and every per-request cap reached. scope is the budget that ran out. |
token.allowance.cost |
counter, USD | model, charge (usage, estimate) |
Cost charged to budgets. estimate means the provider reported no usage. |
token.allowance.tokens |
counter | model, charge |
Tokens charged to budgets. |
token.allowance.estimate.ratio |
distribution summary | model |
Reported tokens divided by the reserved estimate. Above 1 means the estimate was too low. |
No meter is tagged with a user, tenant or session id. Turn them off with management.metrics.enable.token.allowance=false.
The tokenallowance endpoint shows where a subject stands. Expose it like any other endpoint (management.endpoints.web.exposure.include: health,tokenallowance) and secure it, since it shows any user's spend.
GET /actuator/tokenallowance/user/alice (add ?plan=pro for a plan's limits; any id works for global):
{
  "scope": "user",
  "subjectId": "alice",
  "plan": null,
  "budgets": [
    {
      "window": "daily",
      "windowStart": "2026-11-08T00:00:00Z",
      "resetsAt": "2026-11-09T00:00:00Z",
      "maxTokens": 100000,
      "maxCost": 1.000000,
      "committed": { "tokens": 4200, "cost": 0.012600 },
      "reserved": { "tokens": 1500, "cost": 0.002000 }
    }
  ]
}
A scope without limits answers 404.
Two application events, both holding subject ids (so never use them as metric tags):
BudgetThresholdReachedwhen a call takes committed spend to 80% or 100% of a limit (seethresholds). It fires once per subject and window, even across instances sharing Redis, and also inobservemode, so100shows who would have been denied.CallSettledafter every model call is charged or released, with the budgets it counted against, the estimate, the reported usage, the charge and the outcome (CHARGED,ESTIMATE_CHARGED,RELEASED). It never holds prompt or response text. Use it for an audit log.
@Async
@EventListener
void onThresholdReached(BudgetThresholdReached event) {
    if (event.percent() == 100) {
        alerts.send(event.key().subjectId(), event.limit(), event.resetsAt());
    }
}
Listeners run on the chat call's thread after the charge, so use @Async for anything slow. To record every decision as well, define a BudgetListener bean. An exception from either kind of listener is logged at WARN and does not fail the call.
Every bean steps aside when your app defines one of the same type:
| Bean | Replace it to |
|---|---|
TokenEstimator |
Count tokens with your model's tokenizer, or reserve output your own way. |
PriceCatalog |
Load prices from somewhere other than properties. |
LimitResolver |
Read limits from your own store (see Plans). |
UsageLedger |
Store spend somewhere other than memory or Redis. See its Javadoc for the atomicity contract. |
SubjectResolver |
Find the user, tenant, session or plan your own way. |
Clock |
Control time in tests. |
Your own ChatClientBuilderCustomizer beans work next to ours. A ChatClient built by hand with ChatClient.builder(chatModel) gets no advisors; add them yourself with .defaultAdvisors(admissionAdvisor, meteringAdvisor).
- Costs are estimates, not invoices. They use the prices you configure and the usage the provider reports. Check them against your bill.
- One price per model. Long-context prices (some models charge more above 200k prompt tokens) are not applied, and a call is priced by the model it asked for, so a router that picks another model, such as
openrouter/auto, is priced wrong. - A budget can be exceeded a little. A finished call is always charged, so with several calls in flight a budget can go over by the difference between their estimates and their real usage. A request can go over
per-request.max-costby at most one call. - A user can be refused with budget left. The whole estimate must fit in what is left, so with 1,024 output tokens reserved, a user with 800 left is refused even if the answer would use 100. Set
estimate.output-tokensto a typical answer length. - The input estimate is rough. One token per three characters of messages, tool calls and tool definitions: too high for English and code (the safe side), about three times too low for Chinese, Japanese and Korean. Each image or other media item reserves 1,600 tokens, enough for one large image; long audio or video needs more. The provider's count replaces the estimate after the call.
- Windows are fixed, not sliding. A user can spend a full minute cap at 10:00:59 and another at 10:01:00.
- In-memory spend is per instance and lost on restart. Use Redis to share it.
- A call that never settles keeps its estimate reserved for an hour, for example on a crashed instance. A call that settles more than an hour after it started may not be charged.
- Timeouts and retries are charged as well as they can be. A call that times out waiting for the answer is charged its estimate, since the provider may have billed it; a timeout while connecting is not. Retries inside the model client, such as the OpenAI client's three by default, are invisible to the advisors: only the last attempt is charged.
- Only
ChatClientcalls are metered. Calling aChatModeldirectly skips both advisors. - Streams: a denied stream makes Spring AI's
MessageAggregatorlog anAggregation Errorline, which can be ignored; onestream()result can be subscribed only once; and a budget that runs out after the first chunk was sent ends the stream instead of becoming a 429.
See CONTRIBUTING.md for how to build, test and send a pull request.