



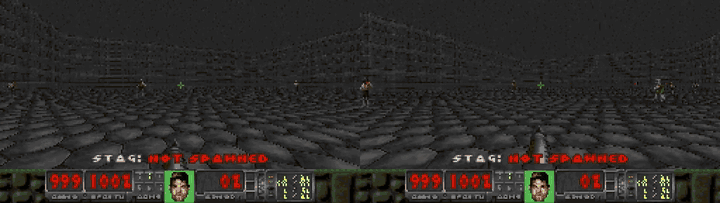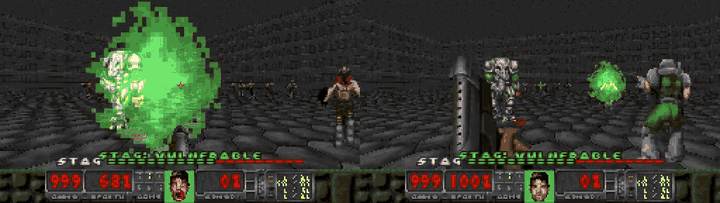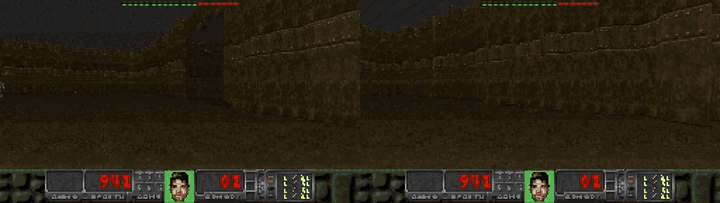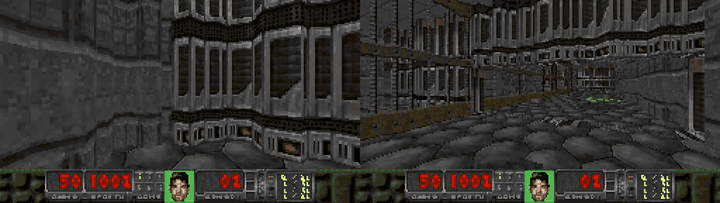
COMRAD is a benchmark of 13 first-person cooperative scenarios built on ViZDoom. Each one isolates a coordination skill: committing to a joint plan, synchronising in time, sharing a commons, swapping roles, or communicating without words. Agents see only their own first-person view.
"Cooperation is the thorough conviction that nobody can get there unless everybody gets there." - Virginia Burden
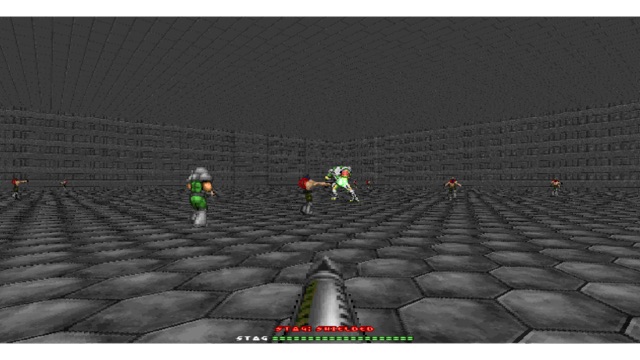 Stag Hunt Arena 2–4 players |
 Rhythm Sync 2 players |
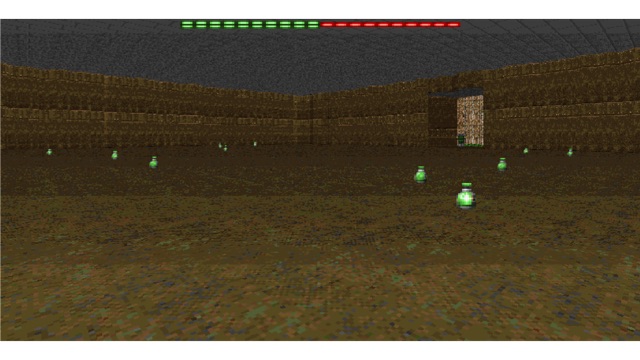 Foraging Commons 2–4 players |
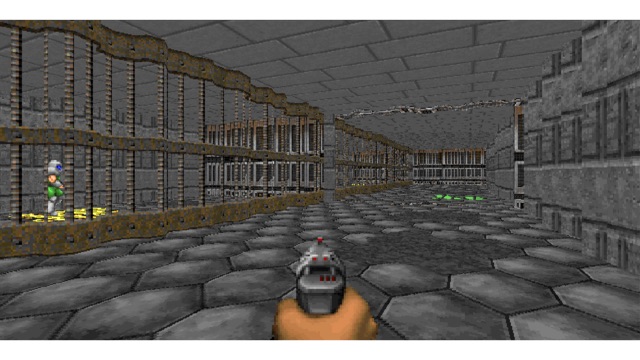 Co-op Puzzle 2 players |
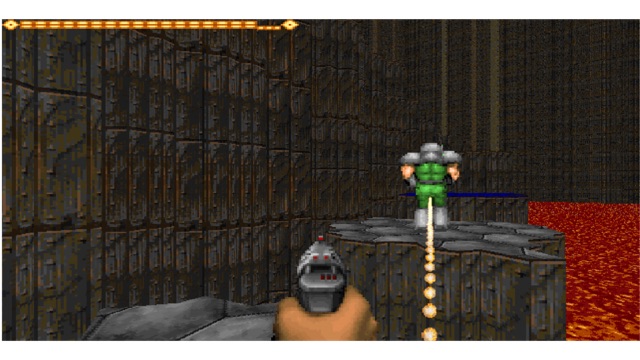 Platform Chain 2 players |
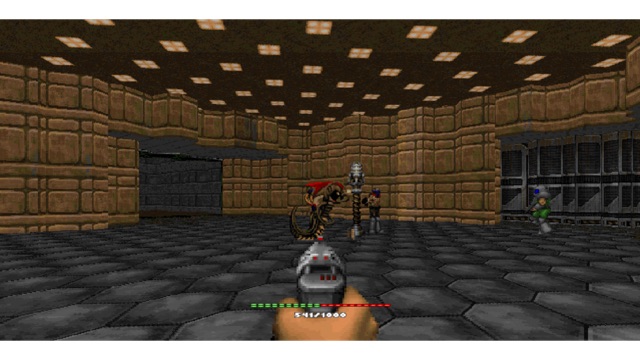 Armory Siege 2–8 players |
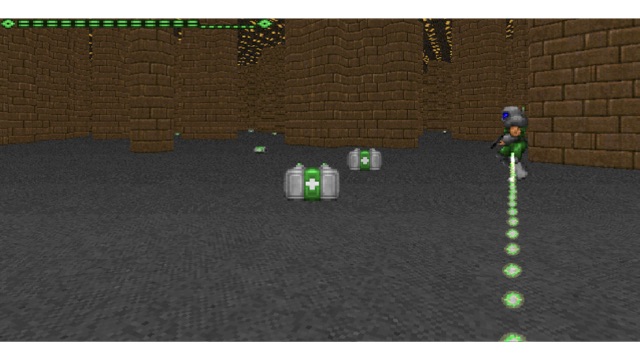 Co-op Health Gathering 2–8 players |
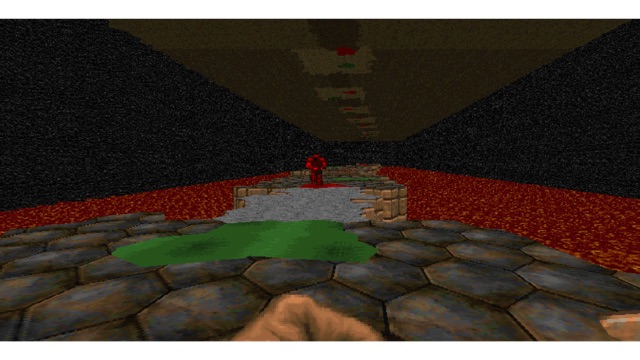 Lava Pit 2 players |
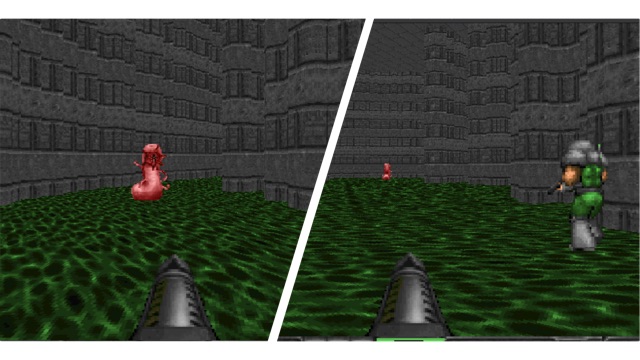 Smart / Dumb Enemies 2–4 players |
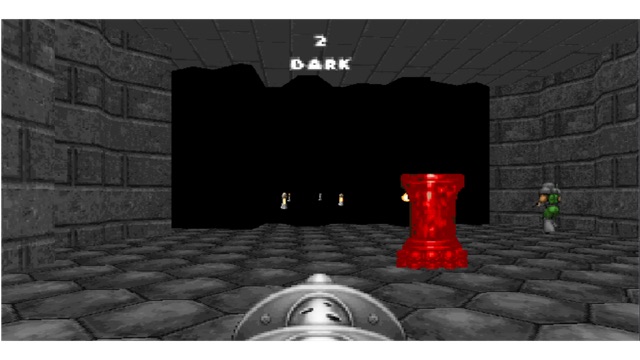 Stealth Labyrinth 2 players |
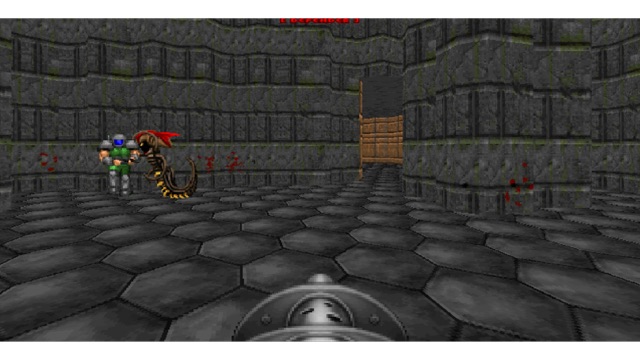 Ammo Carrier 2 players |
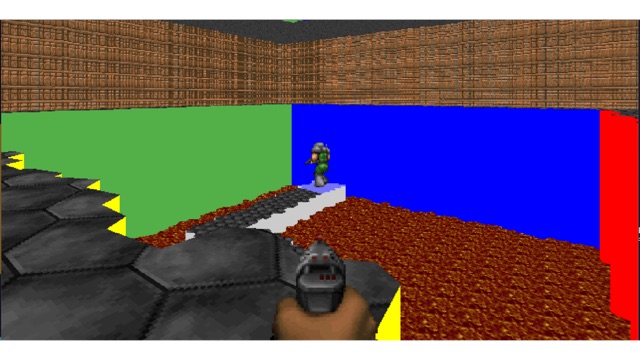 Lava Maze 2 players |
pip install comrad-benchRequires Python 3.11 or 3.12 on Linux or macOS. The ViZDoom engine comes with the vizdoom wheel.
COMRAD scenarios are standard PettingZoo and Gymnasium environments, so you can train them with any MARL library.
import comrad

env = comrad.parallel_env("stag_hunt_arena")
observations, infos = env.reset(seed=42)

while env.agents:
    actions = {agent: env.action_space(agent).sample() for agent in env.agents}
    observations, rewards, terminations, truncations, infos = env.step(actions)

print("score:", {agent: info.get("true_objective") for agent, info in infos.items()})
env.close()
Gymnasium, with per-agent lists:
import gymnasium as gym
import comrad  # registers comrad/<scenario>-v0

env = gym.make("comrad/stag_hunt_arena-v0", num_agents=2)
observations, infos = env.reset(seed=42)
See the quickstart and API reference for options such as num_agents, shared_reward and render_mode.
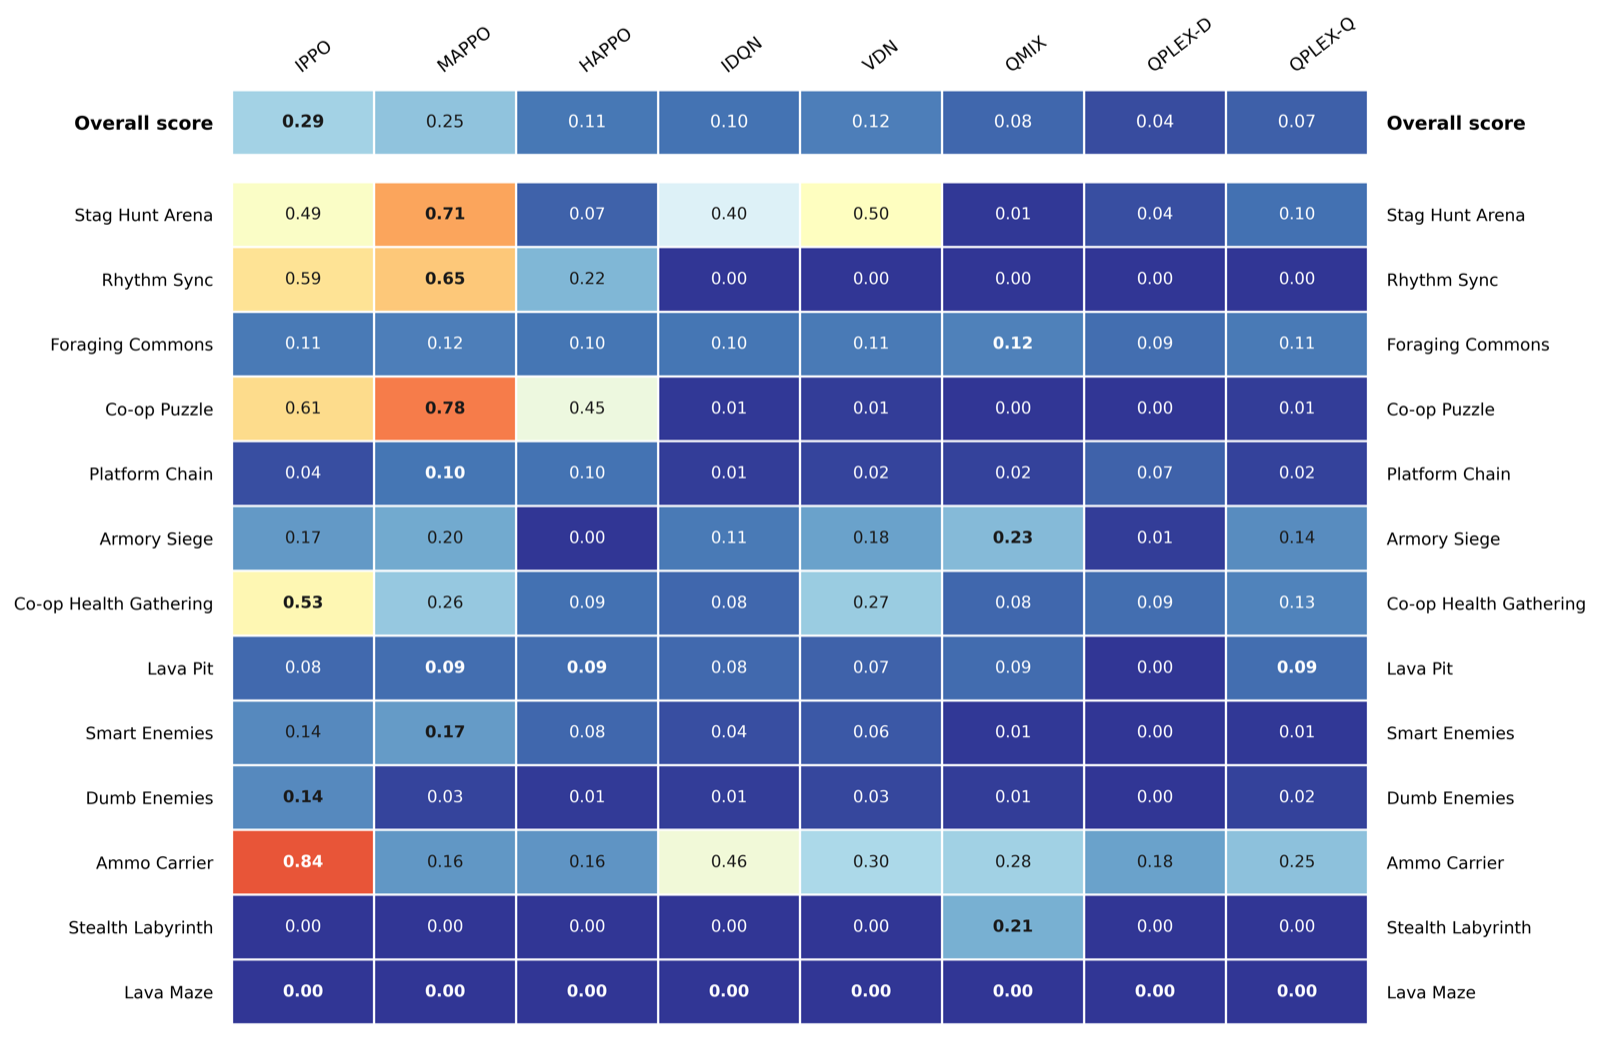
The heatmap shows seven MARL algorithms on every scenario. More results →
The package includes a modified Sample Factory with IPPO, MAPPO, HAPPO, IDQN, VDN, QMIX and QPLEX:
python -m comrad.train --env=stag_hunt_arena --algo=MAPPO --train_for_env_steps=10000000See the per-algorithm commands and how to reproduce the paper.
https://ttomilin.github.io/COMRAD/: scenarios, API, integrations, training, and contributing.
https://lmbored.github.io/comrad_site/: Project page. Visit for a playable demo, scoreboard, and paper overview.
@misc{comrad,
  title  = {COMRAD: A Benchmark for Embodied Multi-Agent Reinforcement Learning},
  author = {Anonymized Authors},
  year   = {2026},
  url    = {https://github.com/TTomilin/COMRAD}
}COMRAD is released under the MIT license. It builds on ViZDoom and Sample Factory. HAPPO follows HARL, IDQN/VDN/QMIX follow PyMARL, and QPLEX follows the official implementation. Experiments were tracked with Weights & Biases and run on the TU/e Supercomputing Center. We thank everyone who contributed to this work.