
High-performance reinforcement learning for GPU-vectorized simulation.
PPO and SAC in PyTorch, thousands of environments per GPU, multi-GPU training, asymmetric actor-critic, ONNX export.
Trains directly on Isaac Lab, vsim, MJLab, EnvPool and MyoSuite.




2.0.0 (unreleased): gymnasium only, Python >= 3.11, EnvPool restored (1.2.6 on Python 3.12+, 1.2.5 on 3.11). See docs/GYMNASIUM_COMPATIBILITY.md for the API changes.
 |
 |
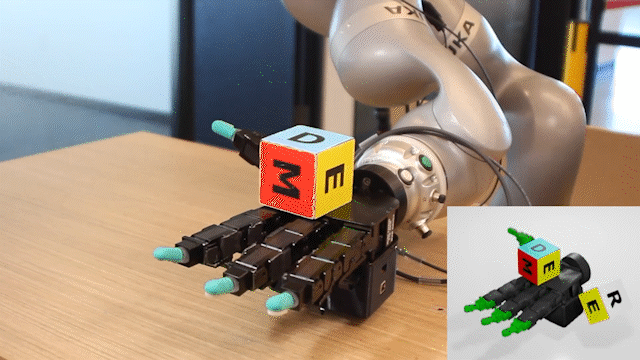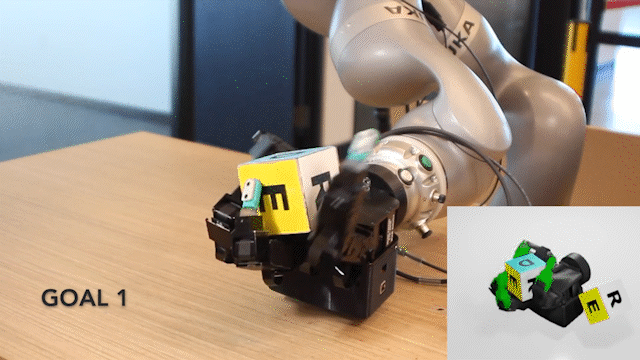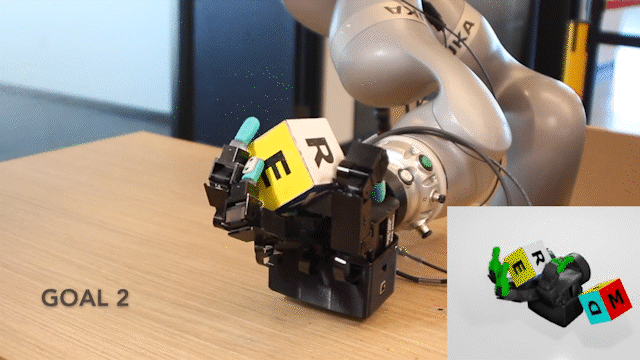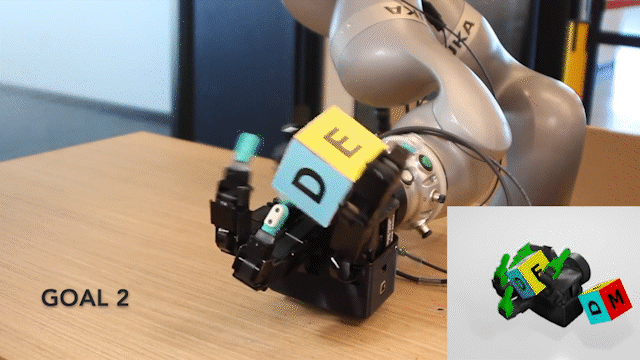
| DeXtreme: Transfer of Agile In-Hand Manipulation from Simulation to Reality (arXiv). Trained in Isaac Gym with rl_games, deployed on the real Allegro hand. | DexPBT: Scaling up Dexterous Manipulation for Hand-Arm Systems with Population Based Training (arXiv). rl_games' population-based training on an Allegro-Kuka system. |
 |
 |
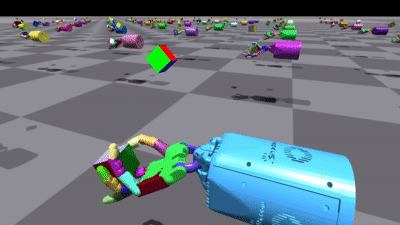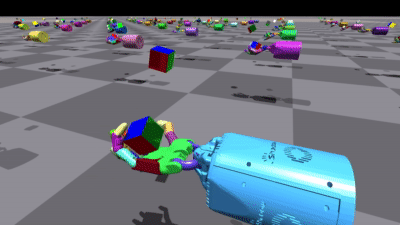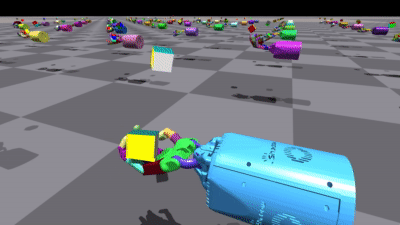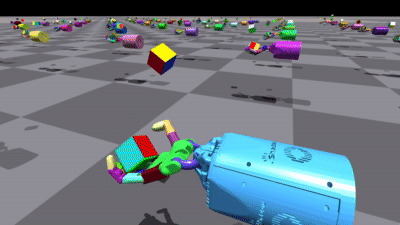
| Isaac Gym: High Performance GPU-Based Physics Simulation For Robot Learning. Shadow Hand cube reorientation, the OpenAI benchmark, trained in hours on a single GPU. | Isaac Gym Humanoid. The whole benchmark suite trains with rl_games; configs and results for rl_games <= 1.6.5 in docs/ISAAC_GYM.md. |
Also trained with rl_games: TriFinger sim-to-real, DextrAH-RGB, Play2Perfect, AMP, OSCAR. Full list under papers and projects.
- Beats the reference trainers on their own tasks, same machine, same budget. MicroDuck: 148 vs 120 final return over three seeds, and their final level reached in 3 minutes instead of 16. Go1 flat velocity: 86.8 vs 83.2. WujiHand reorientation: 19.1–20.1 vs 16.9 goal reaches per episode over three seeds, the reference's score in 1.3–1.4 h instead of 2.1 h, 21.1 on two GPUs. Lift-Cube-Yam: success 0.85 vs 0.72.
- Built for GPU simulators. One process drives thousands of environments. Asymmetric actor-critic with a separate central-value critic, RNN policies, Triton GAE,
torch.compile, DistributedDataParallel multi-GPU, population-based training, self-play, ONNX export, a live viewer with keyboard command control. - Proven in sim-to-real. DeXtreme, DexPBT, TriFinger, DextrAH-RGB and Play2Perfect trained their policies with rl_games.
- SAC too. Matches or exceeds published reference scores at 1M frames on HalfCheetah, Ant and Humanoid, and keeps improving past that budget.
The task plugin runs on mjlab 1.6 from our fork, ViktorM/microduck_rl (branch rl-games, the default), which also carries the ONNX exporter and the deployment guide; install steps in docs/MJLAB.md.
 |
 |
| Forward 0.4 m/s, the shipped config's policy. The overlay shows the commanded and the measured body-frame velocity. | Same environment, reward terms and 4096 x 24 geometry as Pollen's rsl-rl reference: rl_games (3 seeds) crosses the reference's final level at 3 min vs 16.3 and finishes at 148 vs 120. |
 |
 |
| Backward 0.4 m/s, same policy. | Turn in place at 1.0 rad/s: measured 1.0 rad/s. |
 |
Speed lane. A tracking-gated curriculum on the forward command, a gait term and a mirror-symmetry loss take the same robot to 0.39 m/s with no falls, against 0.33 m/s for Pollen's released policy under the same 0.8 m/s command. Recipe in docs/MJLAB.md. |
 |
 |
| Go1 flat velocity, the shipped config's policy: 1.0 m/s, a 0.7 rad/s turn, then 1.5 m/s (1.1 m/s achieved). | Against mjlab's rsl-rl reference, first 5000 of 10k iterations: 97.0 vs 94.0; final 86.8 vs 83.2 after the stage-2 command range opens. |
 |
 |
| WujiHand in-hand reorientation (wuji-mjlab), unmodified task; the exported ONNX policy passes the project's sim2sim deployment protocol. | 19.1–20.1 vs 16.9 goal reaches per episode at the same training budget (three seeds), the reference's final score in 1.3–1.4 h instead of 2.1 h; 21.1 on two GPUs. Recipe and stability notes in docs/MJLAB.md. |
 |
Go1 rough terrain. The asymmetric central-value critic on the privileged observation group lifts the reward from about 45 to about 60. The same recipe trains Lift-Cube-Yam manipulation to 0.85 episode success vs 0.72 for the reference. Recipes, configs and the live viewer: docs/MJLAB.md. |
 |
 |
| G1 flat velocity: 1.0 m/s (1.05 achieved), a 0.5 rad/s turn, 0.8 m/s, no falls. 8192 environments on two GPUs with DistributedDataParallel. | Training reward of that run; the clip is the iteration-4959 checkpoint. Humanoid reward is a poor proxy for walking, so the G1 config is documented by behaviour rather than by a reward comparison. |
 |
 |
| Task (1M frames, 3 seeds) | rl_games SAC | Reference SAC |
|---|---|---|
| HalfCheetah | 11,140 ± 665 | 10,469 ± 1,123 |
| Ant | 4,706 ± 1,379 | 4,623 ± 984 |
| Humanoid | 5,195 ± 198 | 5,044 ± 390 |
Humanoid keeps improving past the 1M-frame budget: a single run extended to 5M frames reaches 7,066, about 40% above the reference mean. Full table, plots and reproduction in docs/SAC_BENCHMARKS.md.
- MJLab (MuJoCo Lab): quadruped, humanoid and MicroDuck locomotion, dexterous manipulation, live viewer play
- EnvPool: high-throughput MuJoCo, Atari and DM Control
- MyoSuite: musculoskeletal control, envpool-vectorized
- DeepMind Control Suite
- StarCraft 2 Multi-Agent Challenge
- NVIDIA Isaac Gym (legacy, rl_games <= 1.6.5)
- Other environments
- Play2Perfect: What Matters in Dexterous Play Pretraining for Precise Assembly? (CoRL 2026): https://play2perfect.github.io/ https://arxiv.org/abs/2606.26428
- DextrAH-RGB: Visuomotor Policies to Grasp Anything with Dexterous Hands: https://dextrah-rgb.github.io/ https://arxiv.org/abs/2412.01791
- DexPBT: Scaling up Dexterous Manipulation for Hand-Arm Systems with Population Based Training: https://sites.google.com/view/dexpbt https://arxiv.org/abs/2305.12127
- DeXtreme: Transfer of Agile In-Hand Manipulation from Simulation to Reality: https://dextreme.org/ https://arxiv.org/abs/2210.13702
- Isaac Gym: High Performance GPU-Based Physics Simulation For Robot Learning: https://arxiv.org/abs/2108.10470
- Transferring Dexterous Manipulation from GPU Simulation to a Remote Real-World TriFinger: https://s2r2-ig.github.io/ https://arxiv.org/abs/2108.09779
- Is Independent Learning All You Need in the StarCraft Multi-Agent Challenge? https://arxiv.org/abs/2011.09533
- Superfast Adversarial Motion Priors (AMP) implementation: https://twitter.com/xbpeng4/status/1506317490766303235 https://github.com/NVIDIA-Omniverse/IsaacGymEnvs
- OSCAR: Data-Driven Operational Space Control for Adaptive and Robust Robot Manipulation: https://cremebrule.github.io/oscar-web/ https://arxiv.org/abs/2110.00704
- EnvPool: A Highly Parallel Reinforcement Learning Environment Execution Engine: https://arxiv.org/abs/2206.10558 and https://github.com/sail-sg/envpool
- TimeChamber: A Massively Parallel Large Scale Self-Play Framework: https://github.com/inspirai/TimeChamber
- PPO with the support of asymmetric actor-critic variant
- SAC
- Support of end-to-end GPU accelerated training pipelines: MJLab (MuJoCo Warp), Isaac Lab. Legacy Isaac Gym: rl_games <= 1.6.5
- Masked actions support
- Multi-agent training, decentralized and centralized critic variants
- Self-play
Implemented in Tensorflow 1.x (was removed in this version):
- Rainbow DQN
- A2C
- PPO
Explore RL Games quick and easily in colab notebooks:
- Mujoco training Mujoco gymnasium training example.
- MJLab training GPU-parallel robot locomotion with MJLab (MuJoCo Warp): trains a Unitree Go1 walking policy in minutes, renders it to video, probes command tracking. Local GPU required.
- MJLab training on Colab Same pipeline for Colab GPUs — L4/A100 recommended (T4 untested).
- Onnx discrete space export example with Cartpole
- Onnx continuous space export example with Pendulum
- Onnx continuous space with LSTM export example with Pendulum
For maximum training performance, PyTorch >= 2.2 with CUDA is recommended.
pip install rl-gamesOr clone the repo and install the latest version from source:
pip install -e .With optional extras (e.g. Atari, Mujoco, EnvPool):
pip install -e ".[atari,mujoco,envpool]"Available extras: atari, mujoco, envpool. (pufferlib is no longer an
extra: its current releases pin numpy<2 / old gymnasium, conflicting with this
project's floors — pip install pufferlib --no-deps; the extra returns with
pufferlib 4.0.)
For high-throughput vectorized MuJoCo / Atari / DM Control training, install the envpool extra and see docs/ENVPOOL.md.
uv is a fast Python package manager. To create a virtual environment and install rl_games:
# 3.12+ resolves envpool 1.2.6; a 3.11 venv falls back to envpool 1.2.5
uv venv --python 3.12
source .venv/bin/activate
uv pip install -e ".[mujoco,envpool]"If you use rl-games in your research please use the following citation:
@misc{rl-games2021,
title = {rl-games: A High-performance Framework for Reinforcement Learning},
author = {Makoviichuk, Denys and Makoviychuk, Viktor},
month = {May},
year = {2021},
publisher = {GitHub},
journal = {GitHub repository},
howpublished = {\url{https://github.com/Denys88/rl_games}},
}uv venv --python 3.11 # project floor (Isaac Lab); .[envpool] resolves envpool 1.2.5 here
source .venv/bin/activate
uv pip install -e ".[atari,mujoco]"NVIDIA Isaac Gym (legacy)
Isaac Gym Preview is end-of-life and not supported by current rl_games
(it requires Python <= 3.8). To run legacy Isaac Gym / IsaacGymEnvs
projects use the last supporting release, rl-games==1.6.5, and its
documentation: https://github.com/Denys88/rl_games/tree/v1.6.5 — see
docs/ISAAC_GYM.md. For current GPU-accelerated
training see MJLab (MuJoCo Warp) and Isaac Lab.
Other
Atari Pong
python runner.py --train --file rl_games/configs/atari/ppo_pong.yaml
python runner.py --play --file rl_games/configs/atari/ppo_pong.yaml --checkpoint nn/PongNoFrameskip.pthrl_games support experiment tracking with Weights and Biases.
python runner.py --train --file rl_games/configs/atari/ppo_breakout_torch.yaml --track
WANDB_API_KEY=xxxx python runner.py --train --file rl_games/configs/atari/ppo_breakout_torch.yaml --track
python runner.py --train --file rl_games/configs/atari/ppo_breakout_torch.yaml --wandb-project-name rl-games-special-test --track
python runner.py --train --file rl_games/configs/atari/ppo_breakout_torch.yaml --wandb-project-name rl-games-special-test -wandb-entity openrlbenchmark --trackrl_games includes the DexPBT-lineage PBT observers
(previously maintained downstream in IsaacGymEnvs and Isaac Lab), usable with any backend
via rl_games.common.pbt — see docs/PBT.md.
We use torchrun to orchestrate any multi-gpu runs.
torchrun --standalone --nnodes=1 --nproc_per_node=2 runner.py --train --file rl_games/configs/ppo_cartpole.yamlWhen Triton is installed, rl_games automatically uses custom Triton kernels for performance-critical operations like GAE (Generalized Advantage Estimation). This replaces the Python for-loop with a single fused GPU kernel.
Triton is enabled by default. To disable:
RLG_NO_TRITON=1 python runner.py --train --file rl_games/configs/mujoco/ant.yamlRun the benchmark to see speedups on your hardware:
python benchmarks/bench_triton_gae.py| Field | Example Value | Default | Description |
|---|---|---|---|
| seed | 8 | None | Seed for pytorch, numpy etc. |
| algo | Algorithm block. | ||
| name | a2c_continuous | None | Algorithm name. Possible values are: sac, a2c_discrete, a2c_continuous |
| model | Model block. | ||
| name | continuous_a2c_logstd | None | Possible values: continuous_a2c_logstd (Gaussian, log-std parametrization), continuous_a2c_tanh, discrete_a2c, multi_discrete_a2c, soft_actor_critic |
| network | Network description. | ||
| name | actor_critic | Possible values: actor_critic or soft_actor_critic. | |
| separate | False | Whether use or not separate network with same same architecture for critic. In almost all cases if you normalize value it is better to have it False | |
| space | Network space | ||
| continuous | continuous or discrete | ||
| mu_activation | None | Activation for mu. In almost all cases None works the best, but we may try tanh. | |
| sigma_activation | None | Activation for sigma. Will be threated as log(sigma) or sigma depending on model. | |
| mu_init | Initializer for mu. | ||
| name | default | ||
| sigma_init | Initializer for sigma. if you are using logstd model good value is 0. | ||
| name | const_initializer | ||
| val | 0 | ||
| fixed_sigma | True | If true then sigma vector doesn't depend on input. | |
| cnn | Convolution block. | ||
| type | conv2d | Type: right now two types supported: conv2d or conv1d | |
| activation | elu | activation between conv layers. | |
| initializer | Initialier. I took some names from the tensorflow. | ||
| name | glorot_normal_initializer | Initializer name | |
| gain | 1.4142 | Additional parameter. | |
| convs | Convolution layers. Same parameters as we have in torch. | ||
| filters | 32 | Number of filters. | |
| kernel_size | 8 | Kernel size. | |
| strides | 4 | Strides | |
| padding | 0 | Padding | |
| filters | 64 | Next convolution layer info. | |
| kernel_size | 4 | ||
| strides | 2 | ||
| padding | 0 | ||
| filters | 64 | ||
| kernel_size | 3 | ||
| strides | 1 | ||
| padding | 0 | ||
| mlp | MLP Block. Convolution is supported too. See other config examples. | ||
| units | Array of sizes of the MLP layers, for example: [512, 256, 128] | ||
| d2rl | False | Use d2rl architecture from https://arxiv.org/abs/2010.09163. | |
| activation | elu | Activations between dense layers. | |
| initializer | Initializer. | ||
| name | default | Initializer name. | |
| rnn | RNN block. | ||
| name | lstm | RNN Layer name. lstm and gru are supported. | |
| units | 256 | Number of units. | |
| layers | 1 | Number of layers | |
| before_mlp | False | False | Apply rnn before mlp block or not. |
| config | RL Config block. | ||
| reward_shaper | Reward Shaper. Can apply simple transformations. | ||
| min_val | -1 | You can apply min_val, max_val, scale and shift. | |
| scale_value | 0.1 | 1 | |
| normalize_advantage | True | True | Normalize Advantage. |
| gamma | 0.995 | Reward Discount | |
| tau | 0.95 | Lambda for GAE. Called tau by mistake long time ago because lambda is keyword in python :( | |
| learning_rate | 3e-4 | Learning rate. | |
| name | walker | Name which will be used in tensorboard. | |
| save_best_after | 10 | How many epochs to wait before start saving checkpoint with best score. | |
| score_to_win | 300 | If score is >=value then this value training will stop. | |
| grad_norm | 1.5 | Grad norm. Applied if truncate_grads is True. Good value is in (1.0, 10.0) | |
| entropy_coef | 0 | Entropy coefficient. Good value for continuous space is 0. For discrete is 0.02 | |
| truncate_grads | True | Apply truncate grads or not. It stabilizes training. | |
| env_name | BipedalWalker-v3 | Envinronment name. | |
| e_clip | 0.2 | clip parameter for ppo loss. | |
| clip_value | False | Apply clip to the value loss. If you are using normalize_value you don't need it. | |
| num_actors | 16 | Number of running actors/environments. | |
| horizon_length | 4096 | Horizon length per each actor. Total number of steps will be num_actors*horizon_length * num_agents (if env is not MA num_agents==1). | |
| minibatch_size | 8192 | Minibatch size. Total number number of steps must be divisible by minibatch size. | |
| minibatch_size_per_env | 8 | Minibatch size per env. If specified will overwrite total number number the default minibatch size with minibatch_size_per_env * nume_envs value. | |
| mini_epochs | 4 | Number of miniepochs. Good value is in [1,10] | |
| critic_coef | 2 | Critic coef. by default critic_loss = critic_coef * 1/2 * MSE. | |
| lr_schedule | adaptive | None | Scheduler type. Could be None, linear or adaptive. Adaptive is the best for continuous control tasks. Learning rate is changed changed every miniepoch |
| kl_threshold | 0.008 | KL threshould for adaptive schedule. if KL < kl_threshold/2 lr = lr * 1.5 and opposite. | |
| normalize_input | True | Apply running mean std for input. | |
| bounds_loss_coef | 0.0 | Coefficient to the auxiary loss for continuous space. | |
| max_epochs | 10000 | Maximum number of epochs to run. | |
| max_frames | 5000000 | Maximum number of frames (env steps) to run. | |
| normalize_value | True | Use value running mean std normalization. | |
| use_diagnostics | True | Adds more information into the tensorboard. | |
| value_bootstrap | True | Bootstraping value when episode is finished. Very useful for different locomotion envs. | |
| bound_loss_type | regularisation | None | Adds aux loss for continuous case. 'regularisation' is the sum of sqaured actions. 'bound' is the sum of actions higher than 1.1. |
| bounds_loss_coef | 0.0005 | 0 | Regularisation coefficient |
| use_smooth_clamp | False | Use smooth clamp instead of regular for cliping | |
| zero_rnn_on_done | False | True | If False RNN internal state is not reset (set to 0) when an environment is rest. Could improve training in some cases, for example when domain randomization is on |
| player | Player configuration block. | ||
| render | True | False | Render environment |
| deterministic | True | True | Use deterministic policy ( argmax or mu) or stochastic. |
| use_vecenv | True | auto | Use vecenv to create environment for player. Auto: True when the env is registered without an env_creator (envpool, pufferlib, plain gymnasium entries, config-registered vecenv_type envs); False for creator-based and unregistered names, so a subclass create_env() override runs |
| games_num | 200 | Number of games to run in the player mode. | |
| env_config | Env configuration block. It goes directly to the environment. This example was take for my atari wrapper. | ||
| skip | 4 | Number of frames to skip | |
| name | BreakoutNoFrameskip-v4 | The exact name of an (atari) gym env. An example, depends on the training env this parameters can be different. | |
| evaluation | True | False | Enables the evaluation feature for inferencing while training. |
| update_checkpoint_freq | 100 | 100 | Frequency in number of steps to look for new checkpoints. |
| dir_to_monitor | Directory to search for checkpoints in during evaluation. |
simple test network
This network takes dictionary observation.
To register it you can add code in your init.py
from rl_games.envs.test_network import TestNetBuilder
from rl_games.algos_torch import model_builder
model_builder.register_network('testnet', TestNetBuilder)
simple test environment example environment
Additional environment supported properties and functions
| Field | Default Value | Description |
|---|---|---|
| use_central_value | False | If true than returned obs is expected to be dict with 'obs' and 'state' |
| value_size | 1 | Shape of the returned rewards. Network wil support multihead value automatically. |
| concat_infos | False | Should default vecenv convert list of dicts to the dicts of lists. Very usefull if you want to use value_boostrapping. in this case you need to always return 'time_outs' : True or False, from the env. |
| get_number_of_agents(self) | 1 | Returns number of agents in the environment |
| has_action_mask(self) | False | Returns True if environment has invalid actions mask. |
| get_action_mask(self) | None | Returns action masks if has_action_mask is true. Good example is SMAC Env |
1.6.5
- Added torch.compile support with configurable modes. Provides 10-40% performance improvement. Requires torch 2.2 or newer.
- Default mode is
reduce-overheadfor balanced compilation time and runtime performance - Configurable via
torch_compileparameter in yaml configs (true/false/"default"/"reduce-overhead"/"max-autotune") - Separate compilation modes for actor and central value networks
- See torch.compile documentation for detailed configuration and mode selection guidance
- Default mode is
- Fixed critical bugs in asymmetric actor-critic (central_value) training:
- Fixed incorrect device reference in
update_lr()method - Fixed infinite loop when iterating over dataset
- Added proper
__iter__method toPPODatasetclass
- Fixed incorrect device reference in
- Fixed variance calculation in
RunningMeanStdto use population variance - Fixed get_mean_std_with_masks function.
- Fixed missing central value optimizer state in checkpoint save/load
- Added myosuite support.
- Added auxilary loss support.
- Update for tacsl release: CNN tower processing, critic weights loading and freezing.
- Fixed SAC input normalization.
- Fixed SAC agent summary writer to use configured directory instead of hardcoded 'runs/'
- Fixed default player config num_games value.
- Fixed applying minibatch size per env.
- Added concat_output support for RNN.
- SAC improvements:
- Fixed missing
gamma_tensorinitialization bug - Removed hardcoded torch.compile decorators (now respects YAML config)
- Optimized tensor operations and removed unnecessary clones
- Fixed missing
- Environment wrapper fixes:
- Fixed tuple/list observation handling for compatibility with various gym environments
- Added proper numpy to torch tensor conversion in
cast_obs - Fixed missing gym import in envpool wrapper
- Ray integration improvements:
- Moved Ray import to lazy loading (only when RayVecEnv is used)
- Added configurable Ray initialization with
ray_configparameter - Added proper cleanup with
close()method for Ray actors - Default 1GB object store memory allocation
1.6.1
- Fixed Central Value RNN bug which occurs if you train ma multi agent environment.
- Added Deepmind Control PPO benchmark.
- Added a few more experimental ways to train value prediction (OneHot, TwoHot encoding and crossentropy loss instead of L2).
- New methods didn't. It is impossible to turn it on from the yaml files. Once we find an env which trains better it will be added to the config.
- Added shaped reward graph to the tensorboard.
- Fixed bug with SAC not saving weights with save_frequency.
- Added multi-node training support for GPU-accelerated training environments like Isaac Gym. No changes in training scripts are required. Thanks to @ankurhanda and @ArthurAllshire for assistance in implementation.
- Added evaluation feature for inferencing during training. Checkpoints from training process can be automatically picked up and updated in the inferencing process when enabled.Enhanced
- Added get/set API for runtime update of rl training parameters. Thanks to @ArthurAllshire for the initial version of fast PBT code.
- Fixed SAC not loading weights properly.
- Removed Ray dependency for use cases it's not required.
- Added warning for using deprecated 'seq_len' instead of 'seq_length' in configs with RNN networks.
1.6.0
- Added ONNX export colab example for discrete and continious action spaces. For continuous case LSTM policy example is provided as well.
- Improved RNNs training in continuous space, added option
zero_rnn_on_done. - Added NVIDIA CuLE support: https://github.com/NVlabs/cule
- Added player config everride. Vecenv is used for inference.
- Fixed multi-gpu training with central value.
- Fixed max_frames termination condition, and it's interaction with the linear learning rate: #212
- Fixed "deterministic" misspelling issue.
- Fixed Mujoco and Brax SAC configs.
- Fixed multiagent envs statistics reporting. Fixed Starcraft2 SMAC environments.
1.5.2
- Added observation normalization to the SAC.
- Returned back adaptive KL legacy mode.
1.5.1
- Fixed build package issue.
1.5.0
- Added wandb support.
- Added poetry support.
- Fixed various bugs.
- Fixed cnn input was not divided by 255 in case of the dictionary obs.
- Added more envpool mujoco and atari training examples. Some of the results: 15 min Mujoco humanoid training, 2 min atari pong.
- Added Brax and Mujoco colab training examples.
- Added 'seed' command line parameter. Will override seed in config in case it's > 0.
- Deprecated
horovodin favor oftorch.distributed(#171).
1.4.0
- Added discord channel https://discord.gg/hnYRq7DsQh :)
- Added envpool support with a few atari examples. Works 3-4x time faster than ray.
- Added mujoco results. Much better than openai spinning up ppo results.
- Added tcnn(https://github.com/NVlabs/tiny-cuda-nn) support. Reduces 5-10% of training time in the IsaacGym envs.
- Various fixes and improvements.
1.3.2
- Added 'sigma' command line parameter. Will override sigma for continuous space in case if fixed_sigma is True.
1.3.1
- Fixed SAC not working
1.3.0
- Simplified rnn implementation. Works a little bit slower but much more stable.
- Now central value can be non-rnn if policy is rnn.
- Removed load_checkpoint from the yaml file. now --checkpoint works for both train and play.
1.2.0
- Added Swish (SILU) and GELU activations, it can improve Isaac Gym results for some of the envs.
- Removed tensorflow and made initial cleanup of the old/unused code.
- Simplified runner.
- Now networks are created in the algos with load_network method.
1.1.4
- Fixed crash in a play (test) mode in player, when simulation and rl_devices are not the same.
- Fixed variuos multi gpu errors.
1.1.3
- Fixed crash when running single Isaac Gym environment in a play (test) mode.
- Added config parameter
clip_actionsfor switching off internal action clipping and rescaling
1.1.0
- Added to pypi:
pip install rl-games - Added reporting env (sim) step fps, without policy inference. Improved naming.
- Renames in yaml config for better readability: steps_num to horizon_length amd lr_threshold to kl_threshold
In addition to the built-in score_to_win, max_epochs, and max_frames stop conditions, training can be terminated by a user-defined callback. The callback receives the algorithm instance and returns True to stop. It is checked once per epoch on rank 0 and broadcast to other ranks under multi-GPU. Works with PPO (continuous and discrete) and SAC.
The signature:
def my_stop(algo) -> bool:
    # algo exposes: epoch_num, frame, last_mean_rewards, mean_rewards,
    # game_rewards, game_lengths, config, ...
    return algo.last_mean_rewards > 18.0 and algo.epoch_num >= 100
There are two ways to wire it in.
Build the agent yourself, set the callback, then call train():
import yaml
from rl_games.torch_runner import Runner

with open('rl_games/configs/atari/ppo_pong.yaml') as f:
    cfg = yaml.safe_load(f)

runner = Runner()
runner.load(cfg)
runner.load_config(runner.default_config)

agent = runner.algo_factory.create(
    runner.algo_name, base_name='run', params=runner.params
)
agent.stop_fn = lambda algo: algo.last_mean_rewards > 18.0 and algo.epoch_num >= 100
agent.train()Pass the callable in the runtime args dict (programmatic), or reference it from YAML by import path (string).
Programmatic:
def my_stop(algo):
    return algo.last_mean_rewards > 18.0 and algo.epoch_num >= 100

runner = Runner()
runner.load(cfg)
runner.run({'train': True, 'stop_fn': my_stop})
YAML — set config.stop_fn to either pkg.mod:function or pkg.mod.function:
params:
  config:
    stop_fn: my_project.stops:reward_plateau
The string is resolved by importlib at training start. args['stop_fn'] (programmatic) takes precedence over config['stop_fn'] (YAML) if both are set.
stop_fn must be a callable taking the algo and returning bool; an ValueError is raised at startup otherwise.
- Some of the supported envs are not installed with setup.py, you need to manually install them
- Starting from rl-games 1.1.0 old yaml configs won't be compatible with the new version:
steps_numshould be changed tohorizon_lengthamdlr_thresholdtokl_threshold
- Running a single environment with Isaac Gym can cause crash, if it happens switch to at least 2 environments simulated in parallel